


What if neural networks now make decisions in code editors, safety systems and other places? Can we really see the circuits that are behind each behavior. OpenAI introduced mechanistic interpretationability research study This method trains the language models to have sparse, internal wiring so that behavior of the model can be described using simple, explicit circuits.

Weight-reduction training for transformers
Most transformer language models are dense. Each neuron writes and reads to multiple residual channels and often features are in superposition. Circuit level analysis is difficult. OpenAI previous works tried to use sparse autoencoders on dense models in order to create sparse feature base. Instead, the new research changes the model base so that it is weight-sparse.
OpenAI’s team teaches decoder-only transformers, using an architectural style similar to GPT 2. The AdamW optimizer is used to optimize each step. After every optimization, the team enforces a sparseness level for all weight matrices and biases, as well as token embeddings. Each matrix is only kept with the entries of largest magnitude. All other entries are zeroed out. An annealing program gradually reduces the number of parameters that are not zero over time, until the target is reached.
A weight that is not zero will be 1 in 1,000. The number of activations is also sparse. Around 1 out of 4 activations is non-zero at an average node. The graph of effective connectivity is very thin, even when the width of the model is wide. The circuit will then be able to map the disentangled channels onto its residual channels.
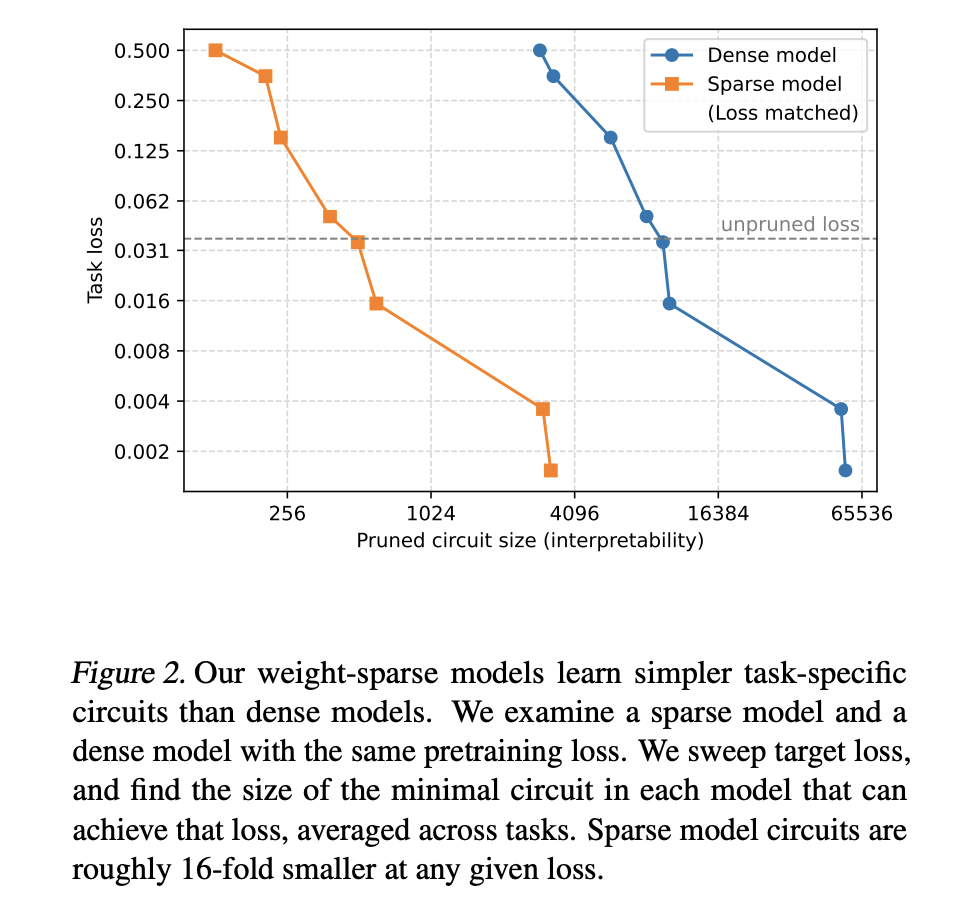
Measurement of interpretability by task-specific pruning
OpenAI’s team doesn’t rely solely on qualitative examples to determine whether the models are more understandable. The OpenAI research team defined a series of simple algorithmic task based upon Python token prediction. In one example, the model must close a Python text with the correct quote character. In set_or_string the model must choose between.add or += depending on whether variables were initialized with a list of values, or as strings.
The search is for the circuit that has the lowest loss and can still complete the task. Node-based pruning. The node can be an MLP neuron in a certain layer, a head of attention, or an residual stream channel. The activation of a pruned node will be replaced by the mean value over pretraining. This is known as mean ablation.
Search is performed using continuous mask parameters at each node, and Heaviside gate style optimized by a surrogate gradient estimator. The count of edges active between nodes retained is used to measure the complexity of circuits. The main metric for interpreting a circuit is the geometric median of edge counts in all tasks.
Examples of circuits using sparse Transformers
Sparse models produce a compact circuit for the single_double_quote problem. In an initial MLP layer one neuron acts as a quotation detector, activating on both single and dual quotes. Second neuron classifies the quote type by separating single and double quotes. The attention head then uses the signals to go back and copy the type of the first quote to the second position.
Circuit graph-wise, this mechanism has 5 residual channels with 2 MLP neuron in layer 0, 1 attention head at a higher layer, and one relevant key channel for the query and only a value channel. This subgraph will still perform the task even if the remainder of the model has been obliterated. This model is rendered useless if the few corners are cut off. In the sense of the operation defined by the paper, the circuit is both sufficient and essential.
Circuits that are recovered from more complex behaviors such as the type tracking of current, a variable within a body function, can be larger in size and still only partly understood. Researchers show an example in which one attention operation is used to write the variable’s name into the token set.() At the definition and a second attention operation, which copies back the type of information that was on the token to a future use of the current. It still produces a circuit diagram that is relatively small.
What you need to know
- By design, transformers are designed to be lightweight.OpenAI trains GPT-2 decoder transformers only so that nearly all weights will be zero. Only 1 out of 1000 weights won’t be zero. By enforcing the sparsity in all weights and biased, including token embeddings which results in thin connectivity graphs.
- The minimum circuit size can be used as a measure of interpretabilityThis work establishes a benchmark for simple Python tasks that require the next token and searches, for each of these, for the smallest possible subnetwork in terms active edges, while still reaching a certain loss. It does this by combining node-level pruning, mean ablation, and straight through mask optimization.
- Out of the reverse engineering, concrete circuits appearOn tasks like predicting quotes, the Sparse Model yields a compact model with few residual channels and 2 MLP neuronal heads. This circuit can be reverse engineered and verified by the authors as being both necessary and enough for the behavior.
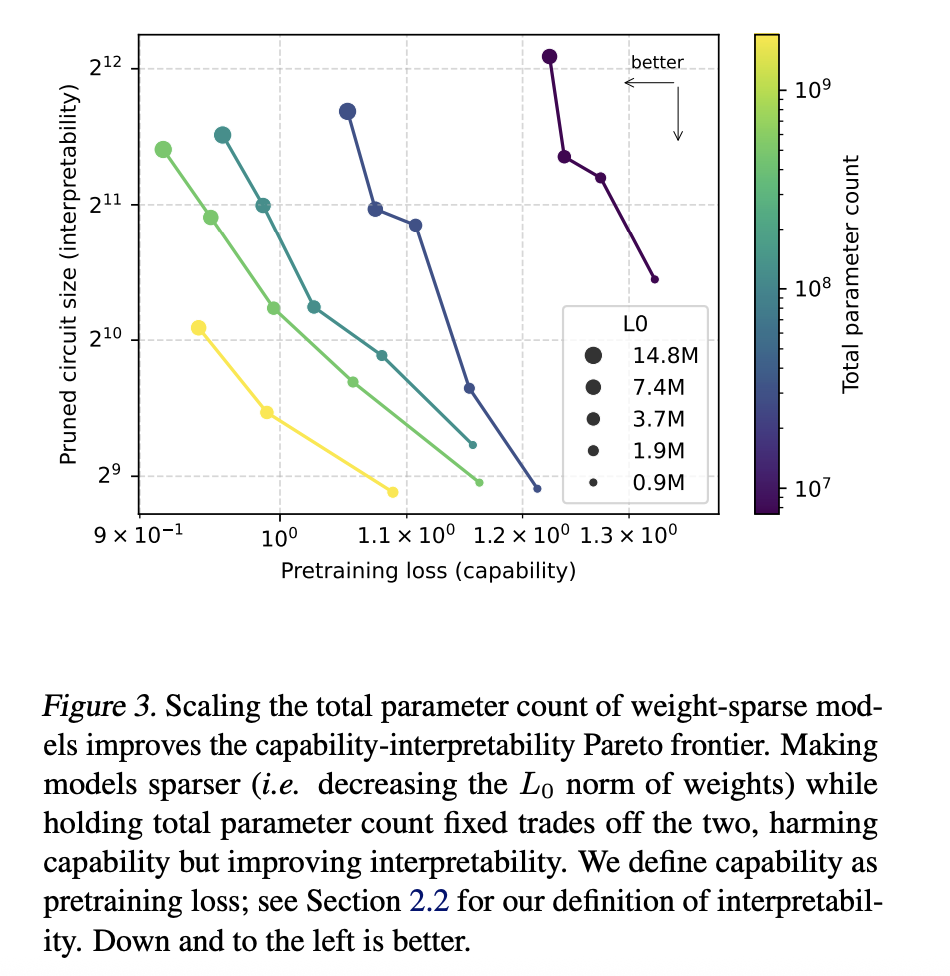
- With Sparsity, you can get smaller circuits with fixed capabilities.Weight sparse model circuits are 16 times smaller at matched loss pre-training levels than dense baselines. This defines a frontier of capability interpretationability where increasing sparsity increases interpretability but reduces raw capability.
OpenAI’s research on weight-sparse transformers represents a practical step towards making mechanistic interpretation operational. The paper enforces sparsity in the base models, transforming abstract circuit discussions into concrete graphs, with quantifiable edge counts and clear need and sufficiency testing, as well as reproducible benchmarks for Python token next tasks. These models may be small and inefficient but they are useful to future debugging processes and safety audits. The research in this study treats interpretability more as an important design consideration than a post-facto diagnostic.
Take a look at the Paper, GitHub Repo You can also find out more about the following: Technical details. Check out our GitHub Page for Tutorials, Codes and Notebooks. Also, feel free to follow us on Twitter Join our Facebook group! 100k+ ML SubReddit Subscribe now our Newsletter. Wait! What? now you can join us on telegram as well.
Michal is a professional in the field of data science with a Masters of Science degree from University of Padova. Michal is a data scientist with a background in machine learning, statistical analysis and data engineering.
