


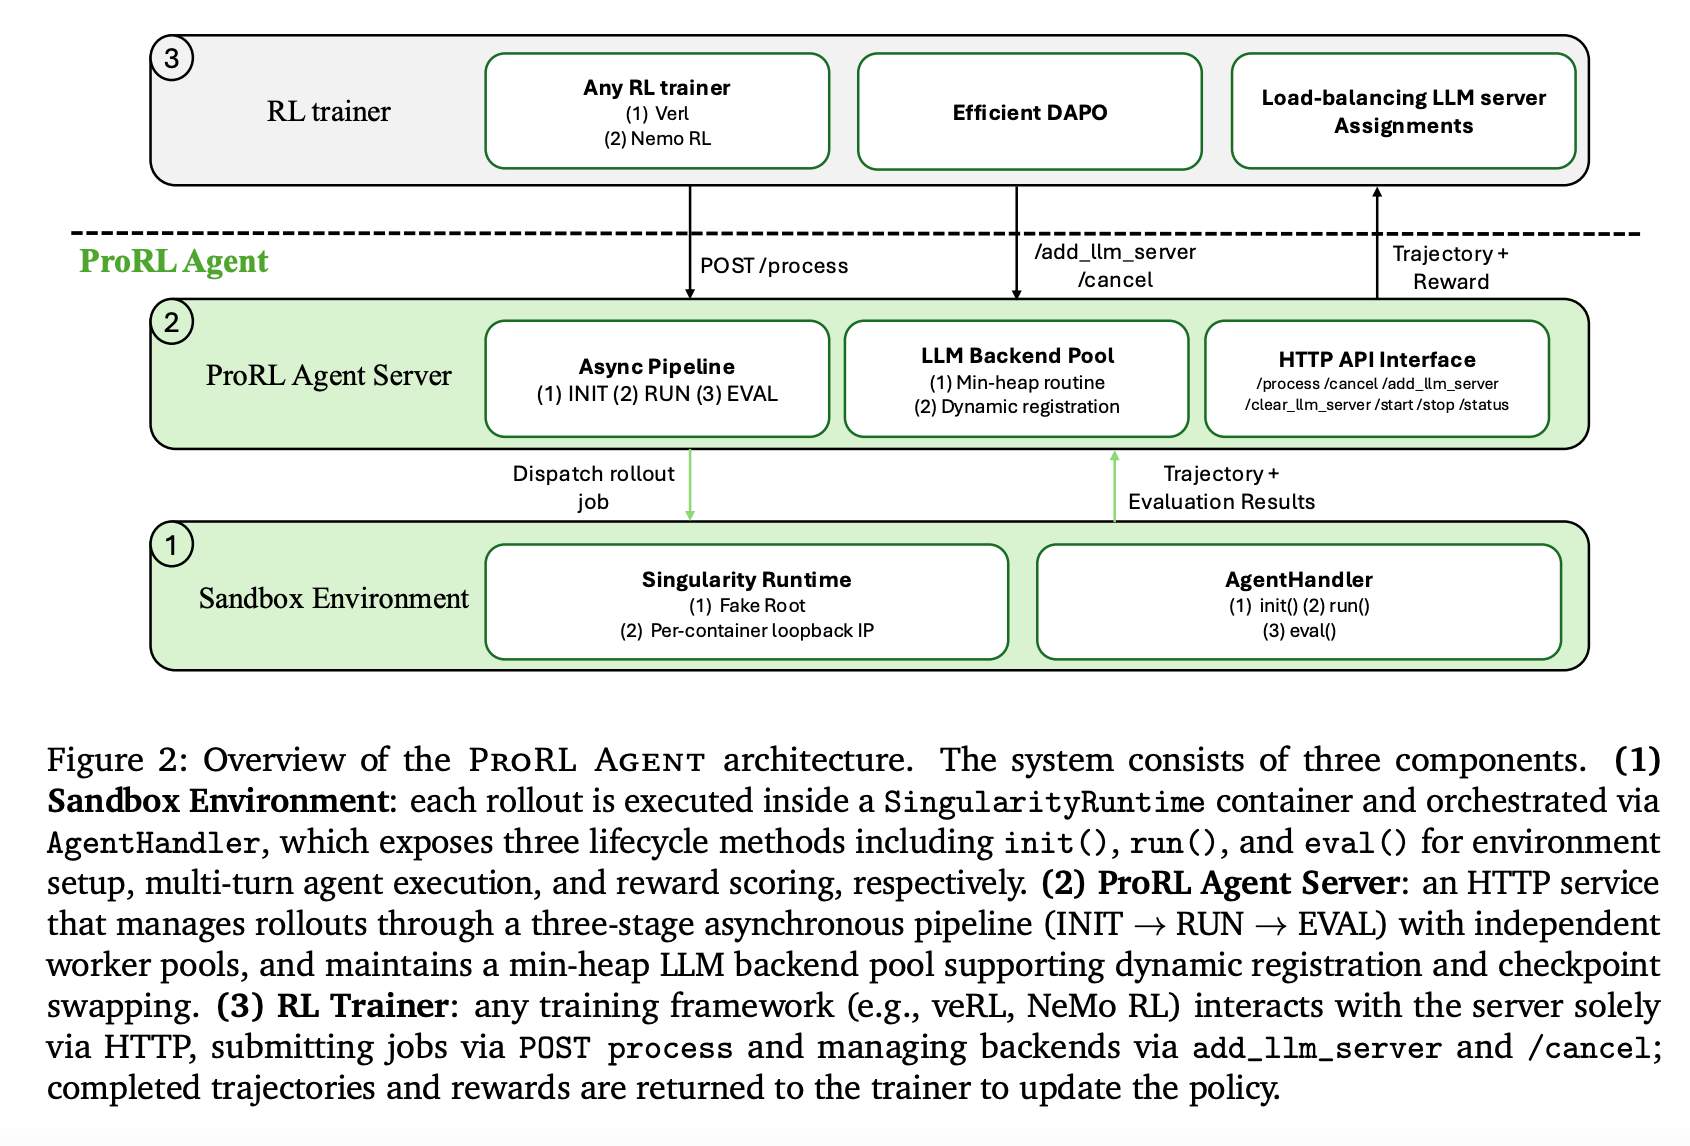
NVIDIA Researchers Introduced PRORL AGENTThe system uses a “Rollout-as-a Service” philosophy to decouple the agentic rollout orchestration from the training loop. By adopting a ‘Rollout-as-a-Service’ philosophy, the system decouples agentic rollout orchestration from the training loop. The architectural change addresses resource conflicts that exist between I/O intensive environment interactions and GPU-intensive updates to policy.
A Tight Coupler is the core problem
The use of iterative tools is used for multi-turn tasks that involve agents interacting with other environments such as operating systems or code repositories. Many existing frameworks—including SkyRL, VeRL-Tool, Agent Lightning, rLLM” GEM—embed rollout control directly within the training process.
Two primary limitations are caused by this tight coupling:
- Contrary System RequirementsThe rollouts require I/O, which requires sandboxes, tool sessions with long durations, and coordination that is asynchronous. The training is GPU intensive, with a focus on gradient synchronization and forward/backward pass. Both processes running simultaneously can cause hardware inefficiency and interfere with each other.
- Maintenance BarriersIt is very difficult to support different runtime environments or migrate to other training backends without changing the execution pipeline.

System Design: Service-based Rollout
PRORL AGENT The service is a stand-alone HTTP server that handles the entire rollout cycle. The RL trainer communicates exclusively with the server via an API. It is agnostic about the underlying deployment infrastructure.
Three-Stage asynchronous pipeline
To maximize throughput, the server orchestrates rollouts through an asynchronous three-stage ‘assembly line’:
- INITInitialization Workers spin up Sandbox Containers and configure Tools
- RunThe rollout worker drives the loop of multi-turn agents and records trajectories.
- EVALWorkers in evaluation evaluate results based on the ground truth and produce rewards signals.
Each stage can be assigned to an independent pool of workers. PRORL AGENT The phases can overlap between different tasks, which prevents the slow execution of tests (such as a complete test suite) from stopping the implementation process.
HPC Compatible Sandboxing and Optimized tools
PRORL AGENT utilizes The singularity Sandbox Infrastructure is a must for Singularity. Singularity is a platform that allows rootless execution.
It includes several optimizations that reduce the tool execution time, which is often a major factor in total deployment times:
- Efficient BashThe tmux terminal multiplexing is replaced by a The ptyprocessThe shell command delay is reduced by 0.78s.
- Direct IPython APIConnects persistent kernels through an in-process interface instead of using network gateways. This eliminates networking overhead.
- Unix Domain SocketsReplaces TCP Loopback communication between agent and execution server within the container in order to reduce additional latency.
Scalable RL: Advanced Features
Infrastructure introduces mechanisms that improve the training stability and equipment utilization.
The Prefix Cache is Reused for Load Balance and Cache Reuse
The server maintains a set of LLM inferences backends, such as vLLM (e.g.), using a heap keyed with assignment counts.. If a task has been assigned, then all calls within the task are sent to that same backend.. This is a strategy that maximizes Use prefix cacheReducing inference times across multiple agent turns.
Token-in/Token-out Communication
To eliminate re-tokenization drift—where the token sequence generated during rollout differs from what is used during training—PRORL AGENT Token IDs are used as the standard representation for the whole process. From the backend of the inference system to the trainer, log-probabilities (and IDs) are transmitted unchanged.
DAPO Optimization
This system is designed to support Dynamic Sample Policy Optimization (DAPO), which filters out ‘non-informative’ prompts that yield uniform rewards. PRORL AGENT Uses an asynchronous refilling mechanism to ensure maximum productivity. Once the number of information prompts has been reached, it will terminate redundant jobs.
SWE-Bench verified Experimental Results
Validation was performed using Qwen3 model across multiple scales. PRORL AGENT Consistently improved performance when compared with reproduced baselines.
| Model Scale | Baseline Reproduced | Agent ProRL (RL) |
| Qwen3-4B | 14.8 | 21.2 |
| Qwen3-8B | 9.6 | 18.0 |
| Qwen3-14B | 15.4 (reproduced baseline) | 23.6 |
SkyRL Agent-14B v0 reported previous result was 21.6
This system demonstrates generality and software engineering in addition to STEM, It is a good idea to use the word “Me” instead of “mean”.” Codes for a better understanding The domains that show steady growth in rewards during RL training. The results of scalability tests confirm that the throughput for rollout increases nearly linearly with each additional compute node..
The Key Takeaways
- Architectural Decoupling: ProRL Agent treats the full agentic rollout lifecycle—including environment initialization, tool execution, and reward scoring—as an independent HTTP service, separating I/O-intensive tasks from GPU-intensive policy training.
- Significant Performance GainsThis infrastructure allowed the Qwen3-8B to almost double its performance (from 9.6% up to 18.0%) on the SWE Bench Verified benchmark, while the Qwen3-14B increased from 15.4% up to 23.6%.
- Reduced System LatencyThe action delay was reduced from 0.78s down to 0.42s by targeted optimizations. This contributed to a near linear scaling of throughput across the compute nodes.
- Elimination of tokenization driftThe framework employs a pipeline of tokens-in/tokens-out communications, which ensures that the exact IDs for the tokens created during the rollout will be passed on to the trainer with no risk of re-tokenization.
- HPC native deploymentProRL Agent, by using Singularity rather than Docker, supports rootless execution as well as native Slurm Integration, which allows large-scale training of agents on high-performance clusters.
Check out the Paper The following are some examples of how to get started: Repo. Also, feel free to follow us on Twitter Don’t forget about our 120k+ ML SubReddit Subscribe Now our Newsletter. Wait! What? now you can join us on telegram as well.
