

AI does all the things at scale, from DOS-attack-level web scraping to producing, or enabling, such vast volumes of scientific analysis submissions that the result’s turning into each a logistical disaster and a crisis of quality, because the signal-to-noise ratio continues to grow to be unnavigable.
Final week, preprint server arXiv announced that it will likely be instituting a brand new rate-limiting coverage for submitters, who will now be capped at two submissions monthly. The measure has been taken, the announcement suggests, within the face of a vertiginous rise in submission charges over a brief time-period:
Month-to-month submissions to arXiv’s cs.AI class from January 2024 to September 2026, displaying a greater than sixfold enhance over the interval. Source
Kat Boboris’s weblog put up saying the transfer, which drew comment at Hacker Information final Thursday, acknowledged that arXiv obtained 40,363 submissions in September 2026 – virtually double the 20,569 obtained in September 2024, and greater than 4 occasions the 9,869 obtained in September 2016.
The most recent month’s submissions, Boboris noticed, additionally generated virtually 9,000 assist tickets for arXiv workers and moderators:
‘Our moderators are observing an increase in thin papers of narrow scope, as well as ‘salami’ papers, the place a single work is damaged up and submitted as a set of smaller papers.
‘There is also a marked increase in dense, AI-written papers. AI tools are making it easy for authors to flood arXiv and other repositories with these low-value papers.’
Already, in Could of this 12 months, arXiv had taken the measure of implementing a one-year ban for unchecked AI content material; and in October of final 12 months, had instructed submitters of survey papers and place papers (each of which may be generated with much less effort than a full educational research) that they would need peer-backing with a purpose to be printed at arXiv.
For the second, the arXiv area’s usually obstructive capping of http requests shouldn’t be an excessive amount of in proof, and one can solely hope that its very helpful RSS feeds survive this ongoing retrenchment. Final week Reddit announced the long-feared whole elimination of its RSS feeds, which can happen from the center of subsequent month. Nevertheless, arXiv’s non-profit standing signifies that there’s little similar capital to be gained by shepherding readers into obligatory website visits, or enforced logins – at the very least, for the second.
Towards the Rising Tide
Within the face of such severe and growing problems across the damaging impact of AI use in science analysis – most particularly concerning AI-related analysis, which has eclipsed all different classes, and risen from obscurity to grow to be a political and economic signifier, recently – a strand of analysis has emerged inspecting methods to counter the decline in high quality of AI-related paper submissions.
The most recent to handle the issue comes within the type of a collaboration between Korea’s Seoul Nationwide College and the College of Minnesota within the US. The paper, titled Science or Slop?: Benchmarking and Mitigating Scientific Slop in AI-Generated Papers, proposes measuring ‘scientific slop’ by failures within the connections between a paper’s claims, proof, citations and construction:
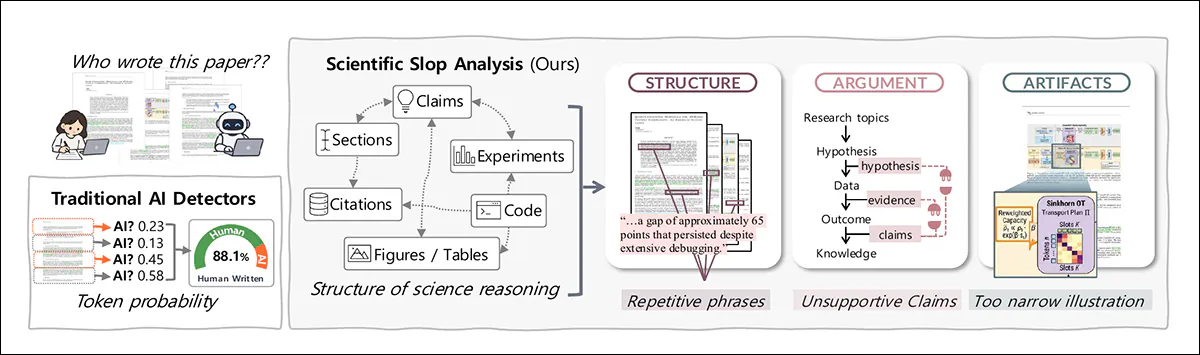
From the brand new paper, an summary of the work’s method to ‘scientific slop’, displaying how failures in construction, argument and supporting artifacts can reveal weaknesses that standard AI-text detectors miss. Source
Not like prior approaches, the brand new system appears past the textual content itself to evaluate whether or not the paper’s claims are correctly supported by its arguments, proof and citations. The authors state*:
‘Each part of a paper can look plausible in isolation, so such breakdowns are invisible to token-level detectors and can only be identified or repaired at the level of the whole paper. To benchmark and mitigate scientific slop, this paper addresses three challenges.
‘First, token-level metrics fail to capture how scientific reasoning connects across a paper. Sections, claims, citations, evidence, and artifacts can each appear plausible while the relationships among them break down. We repeatedly observe such failures in end-to-end AI-generated papers, and ICLR reviewers already penalize them even in human-written submissions.
‘Second, detection of these patterns remains unmeasured. Existing test sets label only the text, so the extent to which detectors, including LLMs that read the entire paper, identify these patterns has never been measured.
‘Third, these patterns are difficult to mitigate reliably. Whereas token-level signals can be removed by paraphrasing, repairing these patterns requires restoring the missing relations without changing the underlying science.’
The authors’ new benchmark, dubbed SciSlopBench, has been embodied into SciSlopHarness, a framework designed to detect and restore failures in a paper’s scientific reasoning, whereas preserving the underlying scientific proof:
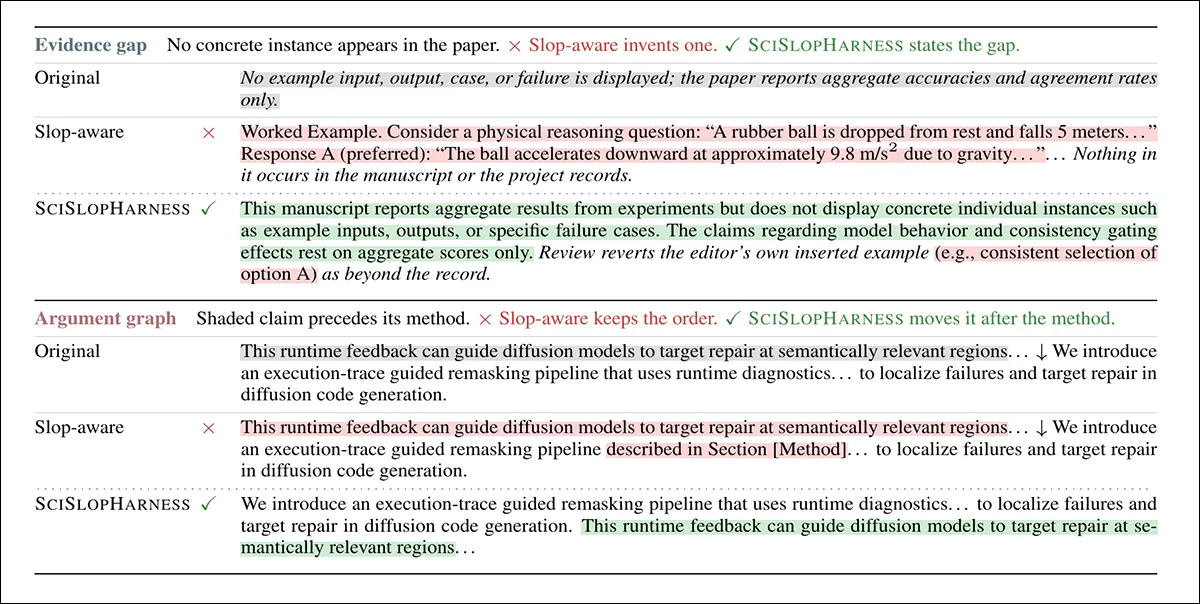
Examples evaluating flawed passages with revisions made by SciSlopHarness. Unsupported additions are rejected, whereas claims are reordered or rewritten the place wanted to higher replicate the proof out there within the paper.
The SciSlopBench benchmark itself was constructed from 390 AI-generated papers, every paired with a human-written paper addressing the same analysis downside and contribution kind.
In assessments, SciSlopBench was used to tell apart between 390 pairs of papers, with every pair consisting of the aforementioned AI-generated paper, and a human-written paper matched for analysis downside and sort of contribution. The benchmark appropriately recognized the AI-generated paper in 85.9% of those comparisons, considerably outperforming standard AI-text detectors.
The authors state:
‘While standard revisions leave residual slop and direct slop-aware prompting triggers reward hacking, SciSlopHarness reduces the remaining AI–human gap by 63% over the strongest revision baseline without requiring human reference targets.
‘Overall, we demonstrate that AI-generated scientific papers leave fundamental traces in their global reasoning, and that responsible mitigation demands strict evidentiary grounding rather than mere prose refinement.’
Along with the contributions made by the paper itself, the authors have operationalized the rules of their new work within the type of a live demo the place customers can submit scientific papers for evaluation of the quantity of AI slop they include.
Curiously, the brand new paper itself, analyzed by the demo, is available in at a ‘moderate’ slop score of 40/100†:
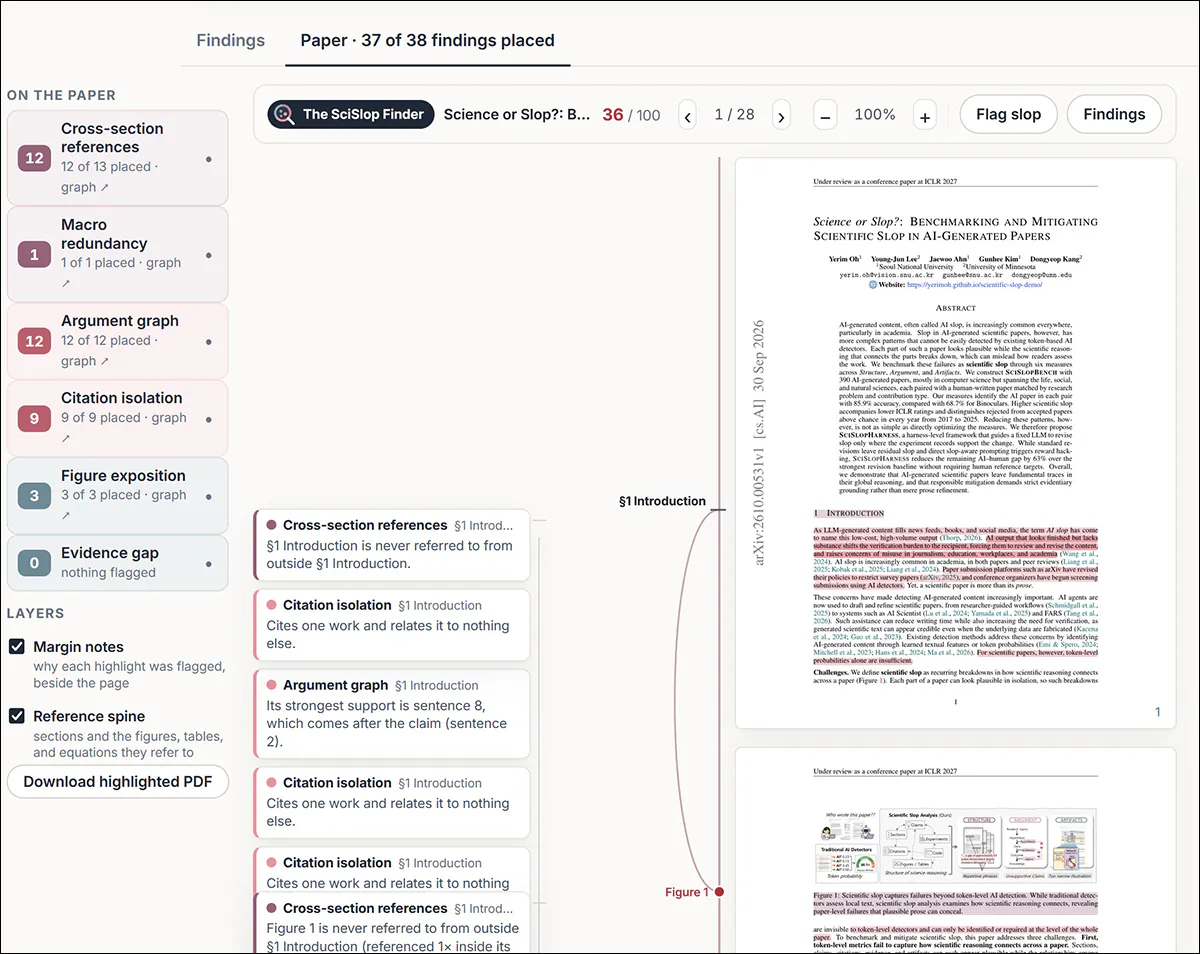
The brand new paper, analyzed by its personal algorithm, will get ‘slop’ areas flagged by the authors’ new course of. Source
Methodology and Knowledge Method
The 2025 collaboration Why Slop Matters described ‘superficial competence’ as a defining attribute of AI slop, the place obvious high quality conceals a scarcity of substance. The brand new work applies this concept extra particularly to scientific papers, defining ‘scientific slop’ as failures that make it troublesome to observe how a research is organized; how its claims are supported; and the way its strategies and proof may be examined, with the failures grouped into construction; argument; and artifacts:
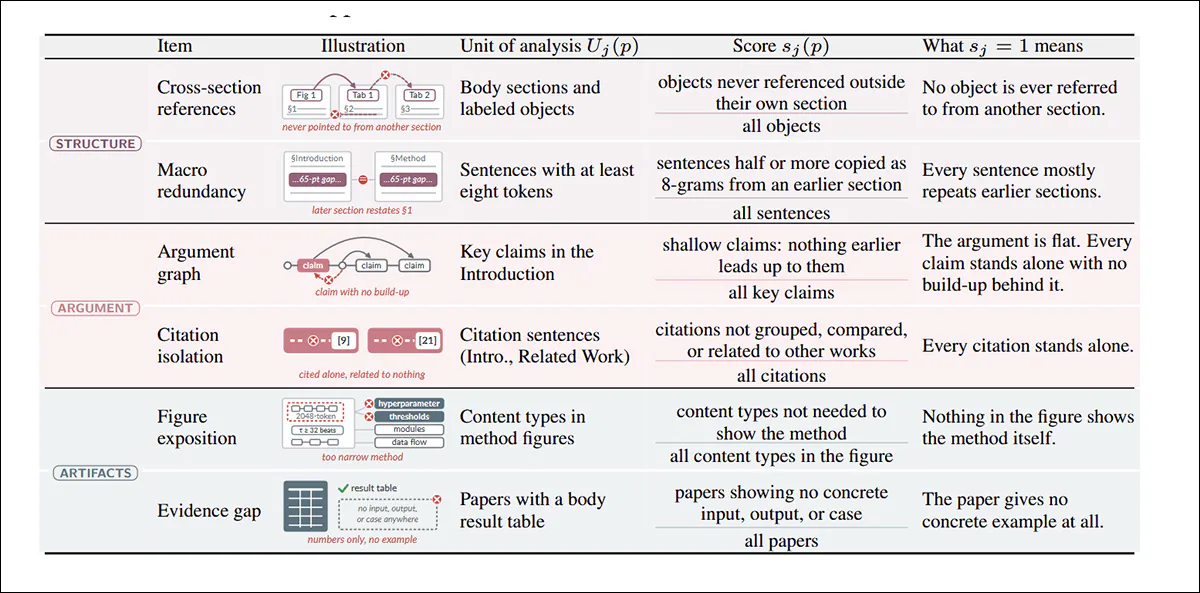
Measurement guidelines for the six sorts of scientific slop used within the benchmark. The desk exhibits what’s examined for every measure, how the rating is calculated, and what the utmost rating of 1 represents, with greater scores indicating extra in depth failures.
The six measures of scientific slop outlined within the paper are cross-section references (whether or not sections refer meaningfully to materials elsewhere within the paper); macro redundancy (whether or not later sections repeat earlier materials); argument graph (whether or not claims are correctly supported by previous reasoning); quotation isolation (whether or not citations are used superficially, with out explaining how the cited works relate to the paper or to one another); determine exposition (whether or not technique figures really clarify the tactic); and proof hole (whether or not reported outcomes are supported by concrete examples).
The benchmark was constructed by pairing AI-generated papers with comparable/equal human-written papers, with the AI papers curated from FARS and the 2025 Agents4Science competitors.
For every machine-generated FARS paper, the researchers searched its citations for a human-authored paper of the identical kind that had been accepted at a top-tier venue, after which chosen the closest match by analysis matter, producing 143 pairs. The Agents4Science papers have been likewise paired with human-written counterparts, producing an additional 247 pairs, and bringing the benchmark to 390 AI-human pairs in whole. The papers span the life, social and pure sciences, although the dataset is weighted closely in the direction of pc science.
For metrics, efficiency was evaluated utilizing PairAcc, which measures how usually the human paper is ranked above its AI counterpart; and AUROC, which measures total separation between human and AI papers throughout completely different thresholds. The authors additionally report detection efficiency when the false-positive price for human papers is fastened at 5%.
Checks
Preliminary assessments in contrast SciSlop towards the AI-text detectors Binoculars; DetectGPT; and NTS††, in addition to the automated evaluate methods AI Scientist Reviewer and CycleReviewer.
For the later revision assessments, 4 baselines have been used: base prompting; Claude Code; reviewer-based refinement; and slop-aware revision. The primary three obtained solely normal directions to enhance the paper, whereas slop-aware revision was moreover given the definitions and areas of detected slop. All have been in contrast with SciSlopHarness beneath equal revision situations.
For implementation, the textual content detectors got the paper’s prose, whereas the opposite strategies obtained the paper supply and, the place required, entry to its code. Binoculars used Falcon-7B base and instruct fashions; DetectGPT used T5-3B to generate 100 perturbations; AI Scientist used Qwen2.5-32B-Instruct; and CycleReviewer used its launched 8B checkpoint. For papers exceeding Falcon’s 2,048-token restrict, non-overlapping home windows have been scored individually and averaged.
The preliminary detection outcomes are detailed within the two tables beneath: SciSlop achieved 85.9% PairAcc, in contrast with 68.7% for Binoculars and 68.5% for the strongest automated reviewer, chopping the error price by greater than half:
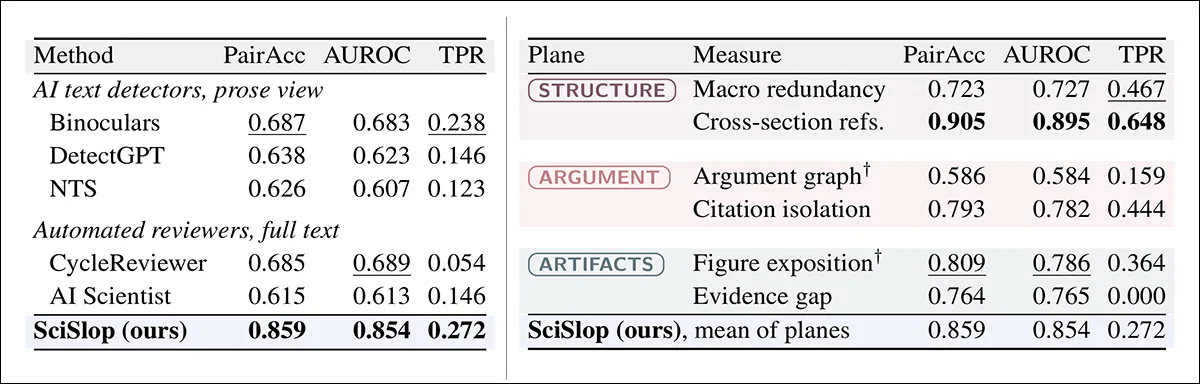
Detection outcomes evaluating SciSlop with AI-text detectors and automatic reviewers, alongside outcomes for its six particular person slop measures. SciSlop achieves the best total PairAcc, whereas cross-section references present the strongest particular person consequence.
Cross-section references carried out notably strongly on their very own, reaching 90.5% PairAcc with out requiring a mannequin, and detecting 65% of AI-generated papers at a 5% false-positive price, in contrast with 24% for Binoculars.
The authors argue that these outcomes point out that relationships throughout the paper present a stronger sign of AI era than standard text-level detection on this dataset, whereas additionally figuring out particular weaknesses that would subsequently be focused for revision.
The connection between scientific slop and human assessments of paper high quality was examined subsequent. As proven within the first column beneath, greater slop was related to decrease ICLR scores for total ranking, soundness, presentation and contribution:
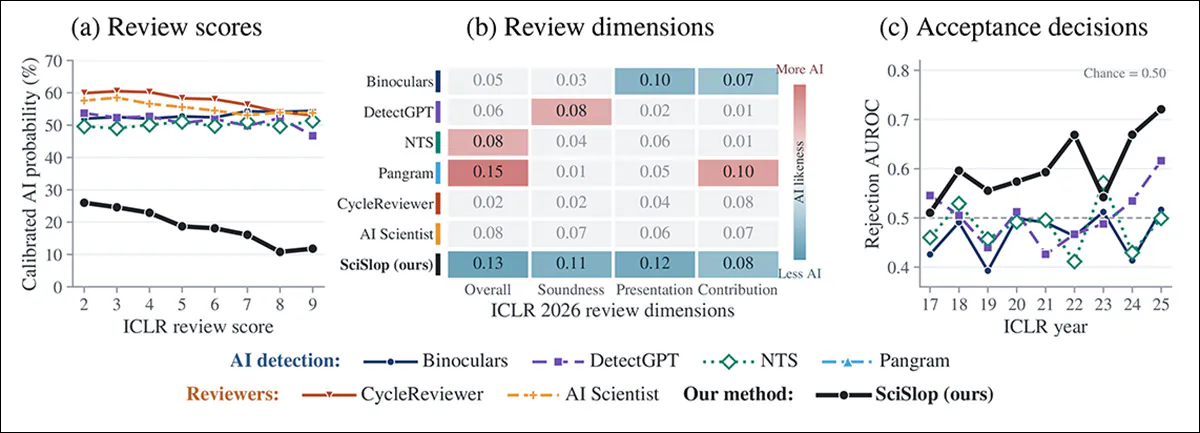
Comparability of SciSlop with AI-text detectors and automatic reviewers towards ICLR evaluate outcomes. The left panel exhibits AI-likeness towards evaluate scores; the middle compares particular person evaluate dimensions; the proper exhibits efficiency in distinguishing rejected from accepted papers throughout 9 years.
Rejected and accepted papers have been additionally distinguished above probability throughout all 9 years examined, whereas standard detectors fell beneath probability in most comparisons.
Scientific slop was subsequently discovered to replicate weaknesses already penalized by human reviewers, reasonably than functioning solely as a sign of AI authorship.
The ultimate assessments examined whether or not SciSlopHarness may take away slop that remained after extra normal revision. As proven beneath, the harness completed closest to the human common throughout all six measures, whereas normal revision usually left substantial slop and direct slop-aware revision generally overcorrected:
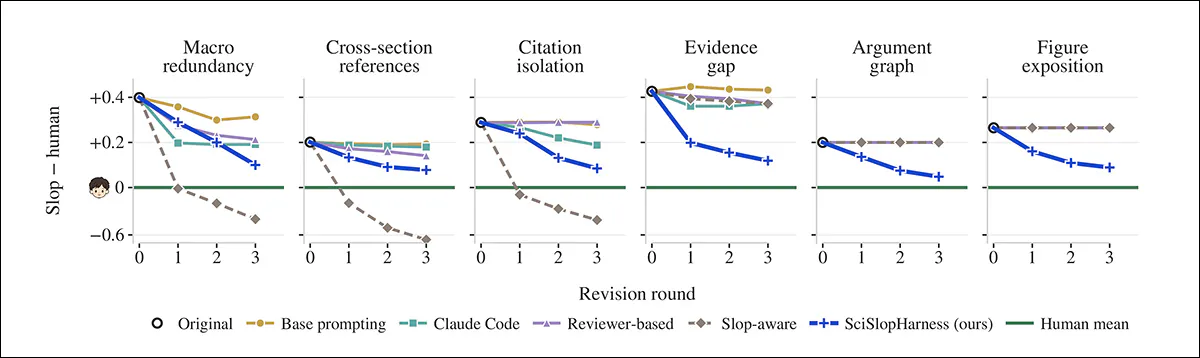
Revision outcomes evaluating SciSlopHarness with 4 baseline strategies throughout the six slop measures. Values nearer to zero are nearer to the human-paper common, with SciSlopHarness usually shifting in the direction of this degree whereas slop-aware revision regularly overshoots it.
Every proposed change was checked towards the paper’s scientific reasoning and supporting proof, with unsupported edits rejected. Throughout the six measures, the remaining hole from human-written papers was decreased by 63% in contrast with Claude Code, the strongest revision baseline.
Conclusion
It was attention-grabbing, in the midst of penning this piece, to notice not solely how poorly this paper scored by itself demo website, however to watch at the very least one instance of a ‘lazy’ or ‘cosmetic’ quotation††, which has recently grow to be a minor however rising curse in analysis papers.
In such instances, past this explicit paper, researchers appear to attract on their very own data reasonably than participating meaningfully with the present literature. But, constrained by conference to ‘show their work’, citations are sometimes equipped with what reads as impatience, even contempt for the method, and sometimes apparently depends on the reader to simply accept a glut of references as a adequate ‘patina’ of provenance, albeit one that will not survive extreme scrutiny.
Arxiv is preventing again towards the AI-driven industrialization of submissions; whether or not there will likely be comparable constraints on AI’s direct involvement in analysis, absent some associated catastrophe of adequate magnitude, stays to be seen.
* The authors’ emphases, not mine – however my conversion the place vital of the authors’ inline citations to hyperlinks.
† The authors don’t declare zero AI use in their very own paper, and detail such usage.
†† It could curiosity the reader to know that I needed to search out an accurate hyperlink myself for the NTS framework, as a result of the hyperlink equipped by the authors was not related – one of many very metrics that SciSlop keys on!
First printed Sunday, October 4th, 2026
