


How can AI systems learn new information without losing what they have learned or having to retrain from the beginning? Google Researchers introduced Nested Learning. This is a machine-learning approach which treats models as collections of small nested problems rather than a single model trained with a loop. It is a way to combat catastrophic forgetting, and to move models towards continuous learning. This will be closer to the biological brain’s ability to manage memory over time.

Nested learning?
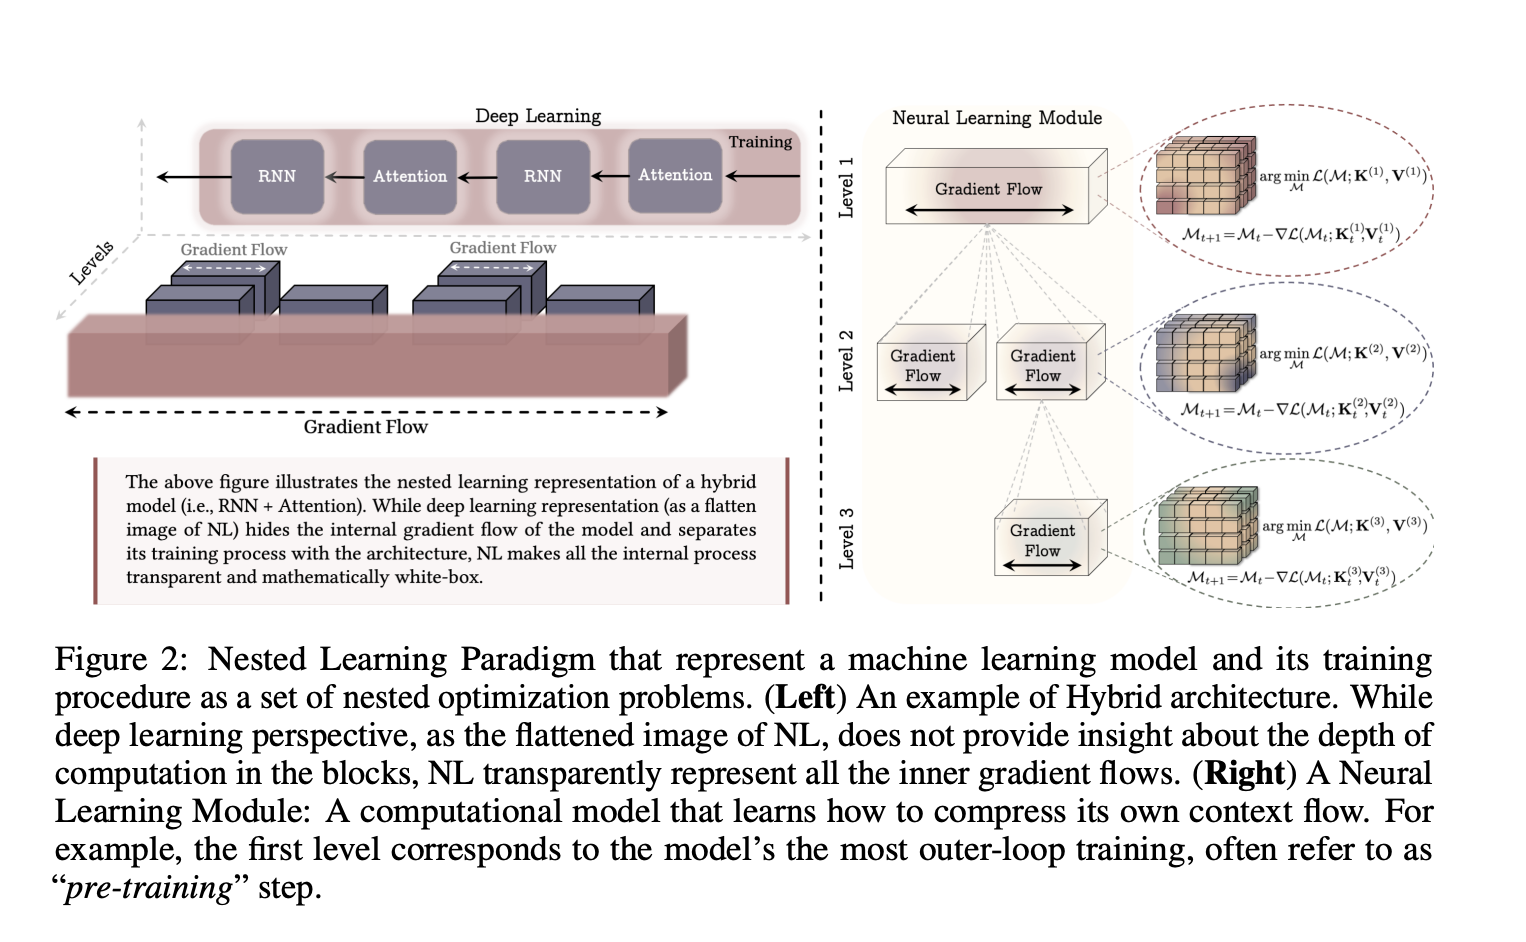
Google’s research report ‘Nested Learning, The Illusion of Deep Learning Architectures’ A complex neural network can be modelled as a collection of coherence optimization problems. They may run simultaneously or nested and are optimised together. Every internal problem is unique, with its own flow of context, inputs or gradients that it observes and update frequency.
Nested Learning forces an order based upon the frequency of updates. The parameters that are updated frequently tend to be at the innermost levels while those with slower updates form the outermost levels. In this hierarchy, each level is defined as a Neural learning module. Each of the levels compresses their own context into parameters. The team of researchers shows that the view includes standard back-propagation using an MLP as well as linear attention as well as common optimizers, which are all examples of associative memories.
Associative memory in this context is defined as any operator which maps values to keys and has an objective that is internal. The team formalizes and formalizes Associative Memory. They then show that Back-Propagation is a gradient descent one-step update which learns an input mapping to local surprises signals.
Deep Optimizers and Associative Memory
Nested Learning proposes redesigning optimizers with richer objectives. Standard momentum is a linear memory of past gradients that can be trained using a similarity dot objective. The internal objective results in a Hebbian update rule which ignores data sample dependencies.
They replaced this similarity object with an L2 regressive loss over gradient features. The result was an update rule which better managed memory capacities and memorized gradient sequences. The researchers then convert the linear momentum map into an MLP, and create Deep Momentum Gradient Descent. This is where a neural memory produces the state of momentum and it can be passed through non-linear functions such as Newton Schulz. In this perspective, the Muon Optimizer is also recovered as a particular case.

Continuum Memory System
In most sequence models attention serves as the working memory of the window in which it is displayed, while feedforwards blocks are used to store long term memories that rarely change after training. Researchers at Nested Learning extend this binary perspective to a Continuum Memory System (CMS).
CMS is defined as a chain of MLP blocks, MLP(f₁) through MLP(fₖ), where each block has its own update frequency and chunk size. These blocks are applied sequentially to an input sequence. The parameters of each block are updated only every C^(ℓ) steps, so each block compresses a different time scale of context into its parameters. Special case: A Transformer standard with only one feedforward blocks is used with k=1.
Instead of one static feedforward level, this construction creates a range of long term memories that are based on frequency. This research relates this directly to the multi-time scale synaptic consolidation and brain processes, in which different parts of a system can learn at varying rates but share a similar architecture.
Hope, an architecture built on titans that is self-modifying
The research team created HOPE to demonstrate that Nested Learning can be applied in recurrent architectures. Titans is an architecture for long-term memories where the neural memory module can be taught to remember unexpected events and help attention pay attention to tokens from long ago.
Titans only has 2 levels of parameter updating, resulting in first-order context learning. Titans can be extended by HOPE in two different ways. It can be self-modifying. Through a self-referential process, it optimizes its memory and in theory, supports unbounded in context learning. Second, the Continuum Memory System is integrated so that updates to memory occur multiple times and are scaled up to larger context windows.

Understand the results
The research team assesses the HOPE model and baselines in language modeling, common sense reasoning, at 3 scales of parameters, 340M 760M and 1.3B. For reasoning, benchmarks include ARC Easy (ARC Challenge), Social IQa and BoolQ for accuracy, as well as Wiki perplexity and LMB for language modeling. Below is Table 1 which reports the results of HOPE and Transformer++.

The Key Takeaways
- Nested Learning uses nested problems to optimize a model, with different updating frequencies. It targets forgetting catastrophically in continuous learning.
- The framework redefines backpropagation as a set of associative memory units that can compress the context flow.
- Nested Learning’s deep optimizers replace the simple comparison of dots with more complex objectives, such as L2 regression. They also use neural memory to create rules that are context-aware and expressive.
- The Continuum Memory System is a model of memory that uses a spectrum MLP blocks which update at different speeds, creating’short, medium and long-range memory’ rather than relying on merely one feedforward static layer.
- The HOPE Architecture, a self-modifying Titans variant built on Nested Learning Principles, has shown improved performance in language modeling, context reasoning and continuous learning compared with strong Transformer baselines and recurrent baselines.
Nested learning is an effective way to reframe deep networks into Neural Learning modules that combine architecture and optimization in one system. Deep Momentum Gradient Descent (DMGD), Continuum Memory System and HOPE provide a tangible path for achieving enriched associative memories and continual improvement in learning. The work makes continual education a design priority.
Take a look at the Paper You can also find out more about the following: Technical Details. Check out our GitHub Page for Tutorials, Codes and Notebooks. Also, feel free to follow us on Twitter Join our Facebook group! 100k+ ML SubReddit Subscribe Now our Newsletter. Wait! Are you using Telegram? now you can join us on telegram as well.

Asif Razzaq, CEO of Marktechpost Media Inc. is a visionary engineer and entrepreneur who is dedicated to harnessing Artificial Intelligence’s potential for the social good. Marktechpost was his most recent venture. This platform, which focuses on machine learning and deep-learning news, is technically solid and accessible to a broad audience. Over 2 million views per month are a testament to the platform’s popularity.
