


Mistral AI has released Voxtral, a family of open-weight models—Voxtral-Small-24B The following are some examples of how to get started: Voxtral-Mini-3B—designed to handle both audio and text inputs. The models are built using Mistral’s Language Modeling Framework and combine ASR with Natural language understanding. Voxtral, released under Apache 2.0, provides solutions for transcriptions, summaries, question-answering, and voice command-based functions.
Voxtral’s design is in line with the demand for more integrated audio processing, both within consumer systems and business applications. The models are designed to simplify common tasks that involve spoken input by offering a language-aware, configurable interface.
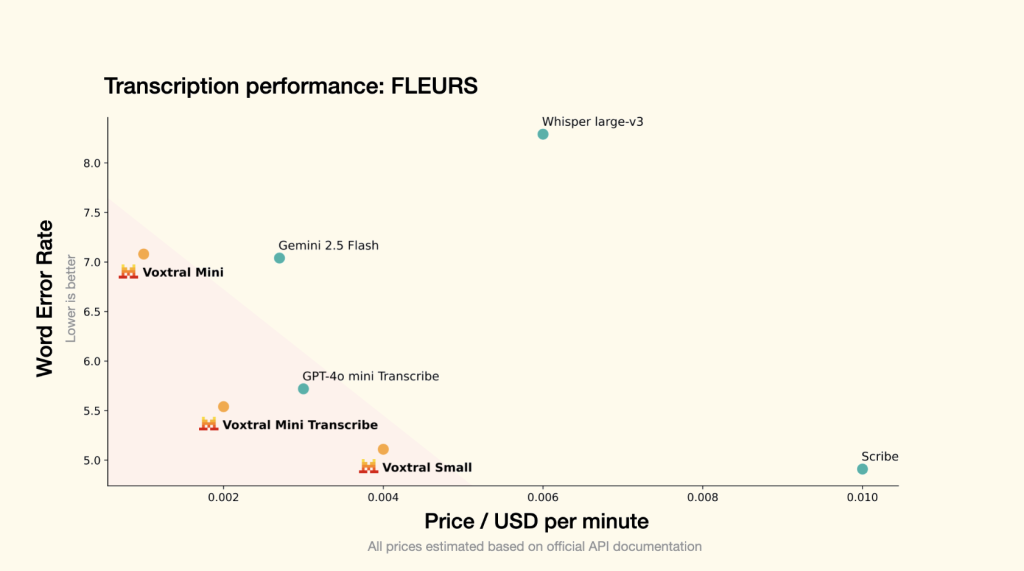
Model Architecture Management and Context Management
Voxtral uses the Mistral Small3.1 as its backbone, and integrates an audio interface to enable processing both of spoken and textual information. Both models support a 32,000-token context window, enabling:
- Audio transcription up to about 30 minutes
- The audio can be extended to up 40 minutes for extended reasoning or summary.
For most use cases, this long-context feature helps to avoid having to truncate or segment input audio.
Key functional Capabilities
- Transcription Performance
- Voxtral offers reliable ASR in a variety of acoustic settings.
- Mistral has dedicated APIs for real-time transcription and streaming.
- Multilingual Processing
- Voxtral includes automatic language detection.
- It works well in many languages. These include English, Spanish. French, Portuguese. Hindi. German. Dutch.
- One model can be used to handle scenarios with multiple languages without any fine tuning.
- The Audio Experience: More Than Transcription
- Models can answer questions about audio content, e.g. “What was the decision made?”The resulting summaries are concise.
- The system can perform these tasks without having to link an ASR model and a separate LLM.
- Voice-based Function Execution
- Voxtral parses user intentions directly via voice, triggering workflows or backend actions accordingly.
- The capability can be used for industrial automation, voice-activated systems and customer service automation.
- Text Mode Support
- Voxtral is a powerful text-only tool that can also perform well on audio tasks. This is due to the fact that it shares a common foundation with Mistral.
- The dual-modality allows for a more fluid user experience in applications with multiple interfaces.
Comparison: Voxtral Model Variants
| Model | Parameters | The input modality | Context Length | Deployment Context |
|---|---|---|---|---|
| Voxtral-Mini-3B | 3B | Audio + Text | 32K tokens | Mobile or edge environments |
| Voxtral-Small-24B | 24B | Audio + Text | 32K tokens | API-based cloud systems |
The 3B variant of the model is optimized for local inference and lightweight deployment, while 24B is designed for use at production levels with more compute resources.
Benchmarks
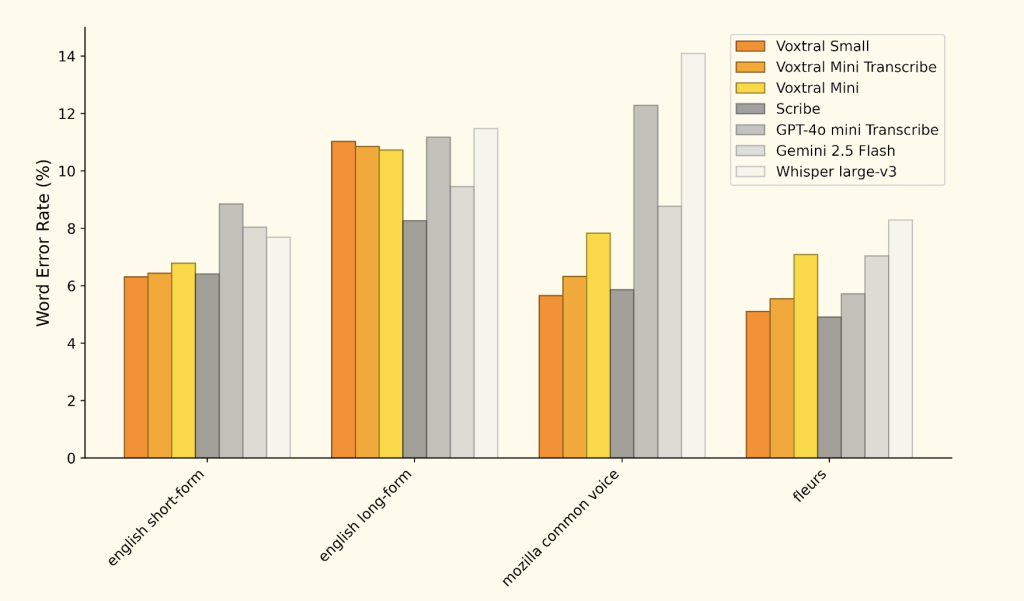
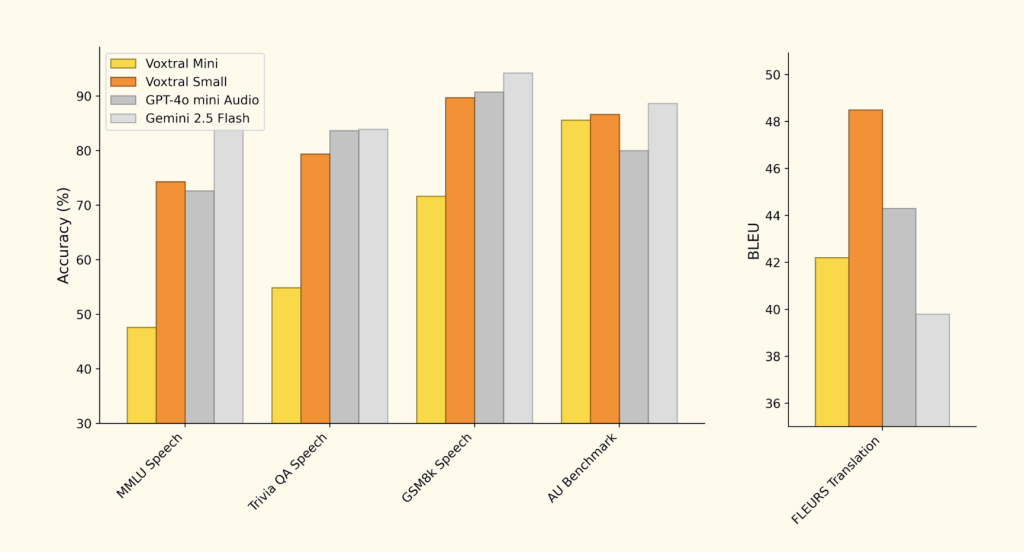
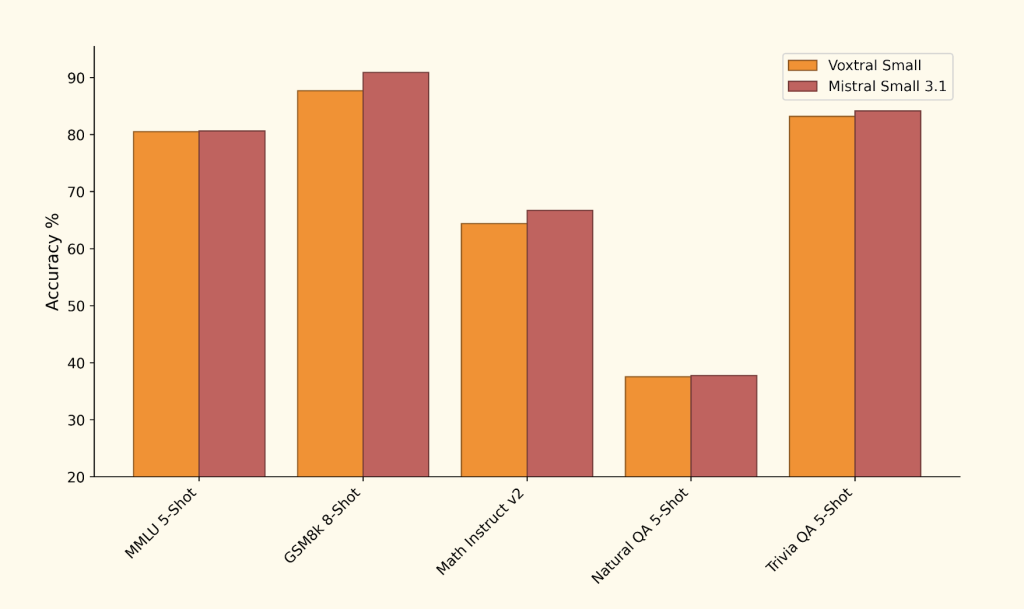
The API interfaces and deployment options
Mistral has optimized transcription-only APIs to help developers who are working with latency-sensitive apps. They can be easily integrated into systems like:
- Transcribing meetings and phone calls
- Translation systems in real-time
- Audio note-taking platforms
- Voice-driven control panels
Voxtral’s models are flexible and can be used in cloud or on-premise deployments.
Its practical application in voice-centered systems
Voxtral, a voice-processing tool, can be used to improve accuracy, context awareness, and the quality of spoken inputs in mobile applications, wearables interfaces, automotive interfaces, support systems and other interfaces. Developers can implement audio understanding pipelines that require fewer components.
The Modular Approach for Audio-Language Integration
Voxtral is a new audio-language model that integrates transcription accuracy, language level reasoning, and command parsing. Its multilingual coverage, long-context support, and flexible licensing make it suitable for a variety of applications—from summarization tools to interactive voice agents.
Take a look at the Technical details, Voxtral-Small-24B-2507 The following are some examples of how to get started: Voxtral-Mini-3B-2507. This research is the work of researchers.
| You can reach the world’s most influential AI developers. One million monthly readers and 500K community builders? Infinite possibilities. [Explore Sponsorship] |

Asif Razzaq, CEO of Marktechpost Media Inc. is a visionary engineer and entrepreneur who is dedicated to harnessing Artificial Intelligence’s potential for the social good. Marktechpost is his latest venture, a media platform that focuses on Artificial Intelligence. It is known for providing in-depth news coverage about machine learning, deep learning, and other topics. The content is technically accurate and easy to understand by an audience of all backgrounds. This platform has over 2,000,000 monthly views which shows its popularity.
