


How do you construct a single speech recognition system that may perceive 1,000’s of languages together with many who by no means had working ASR (automated speech recognition) fashions earlier than? Meta AI has launched Omnilingual ASR, an open supply speech recognition suite that scales to greater than 1,600 languages and might be prolonged to unseen languages with only some speech textual content examples, with out retraining the mannequin.
Information and language protection
The supervised coaching knowledge comes from a mixed corpus known as AllASR. AllASR incorporates 120,710 hours of labeled speech paired with transcripts throughout 1,690 languages. This corpus merges a number of sources, together with open supply datasets, inner and licensed corpora, associate created knowledge, and a commissioned assortment known as the Omnilingual ASR Corpus.
The Omnilingual ASR Corpus contributes 3,350 hours of speech for 348 languages, with knowledge collected via discipline work with native organizations and audio system in areas equivalent to Africa and South Asia. Prompts are open ended, so audio system produce pure monologues in their very own language as an alternative of studying mounted sentences, which supplies extra practical acoustic and lexical variation.

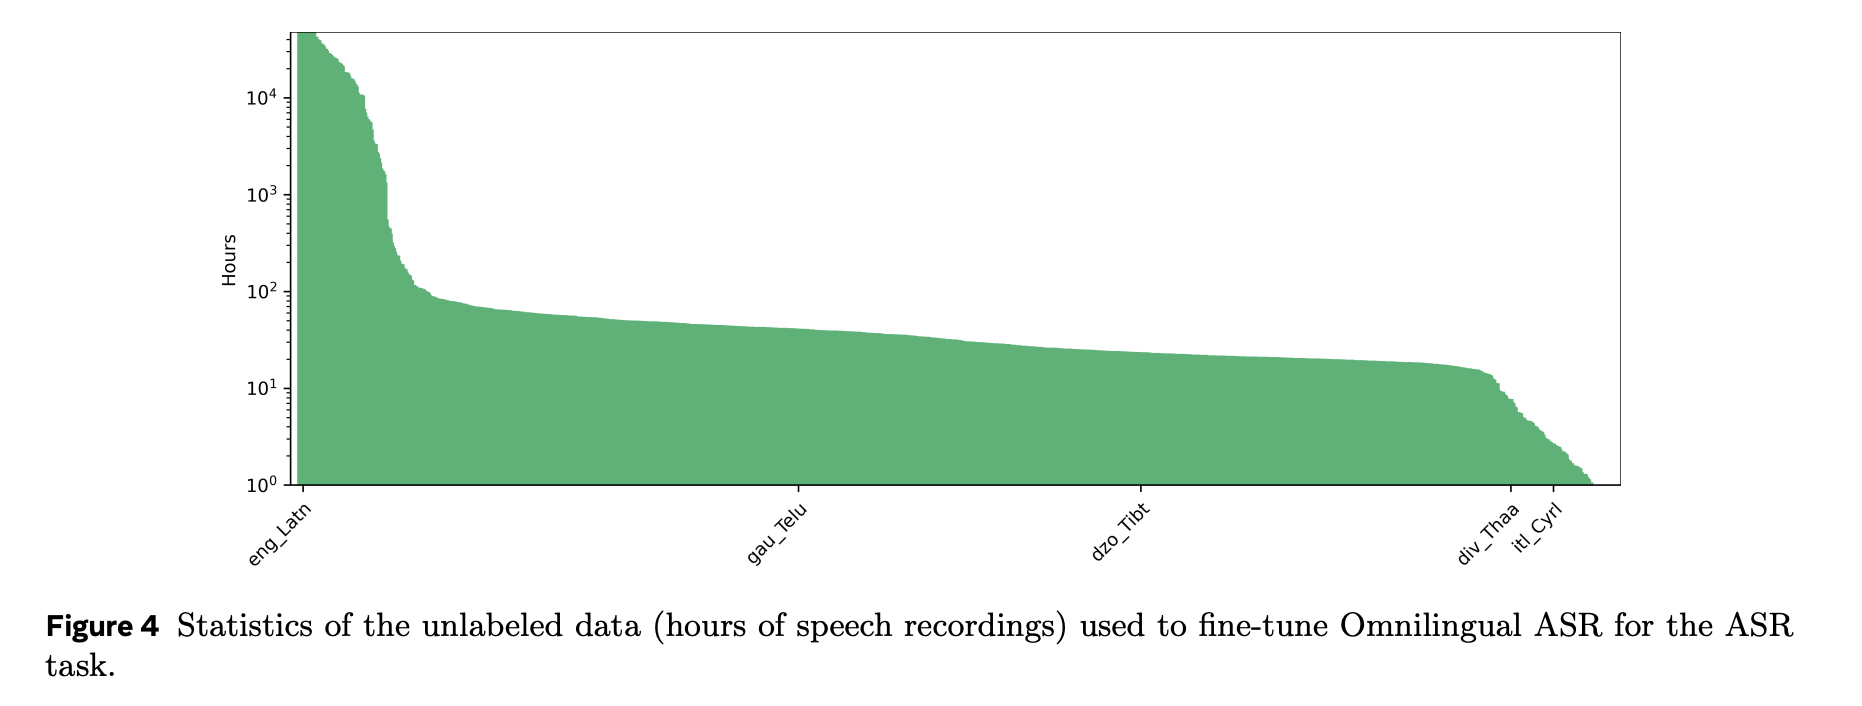
For self supervised pre coaching, the wav2vec 2.0 encoders are educated on a big unlabeled speech corpus. The pre coaching dataset incorporates 3.84M hours of speech with language identification throughout 1,239 languages, plus one other 460K hours with out language identification. The full unlabeled audio used for pre coaching is subsequently about 4.3M hours. That is nonetheless considerably smaller than the 12M hours utilized by USM, which makes the reported outcomes extra attention-grabbing from an information effectivity perspective.
Mannequin household
Omnilingual ASR exposes 3 primary mannequin households that every one share the identical wav2vec 2.0 speech encoder spine:
- SSL encoders (OmniASR W2V)
Self supervised wav2vec 2.0 encoders with the next parameter counts
•omniASR_W2V_300Mwith 317,390,592 parameters
•omniASR_W2V_1Bwith 965,514,752 parameters
•omniASR_W2V_3Bwith 3,064,124,672 parameters
•omniASR_W2V_7Bwith 6,488,487,168 parameters. These fashions are educated with the usual wav2vec 2.0 contrastive goal. After coaching, the quantizer is discarded and the encoder is used as a speech illustration spine. - CTC (connectionist temporal classification) ASR fashions
CTC fashions add a easy linear layer on high of the encoder and prepare finish to finish with a personality stage CTC loss. The launched CTC fashions vary from 325,494,996 parameters to six,504,786,132 parameters and attain actual time components as little as 0.001 for the 300M mannequin on A100 for 30 second audio with batch dimension 1. - LLM ASR fashions
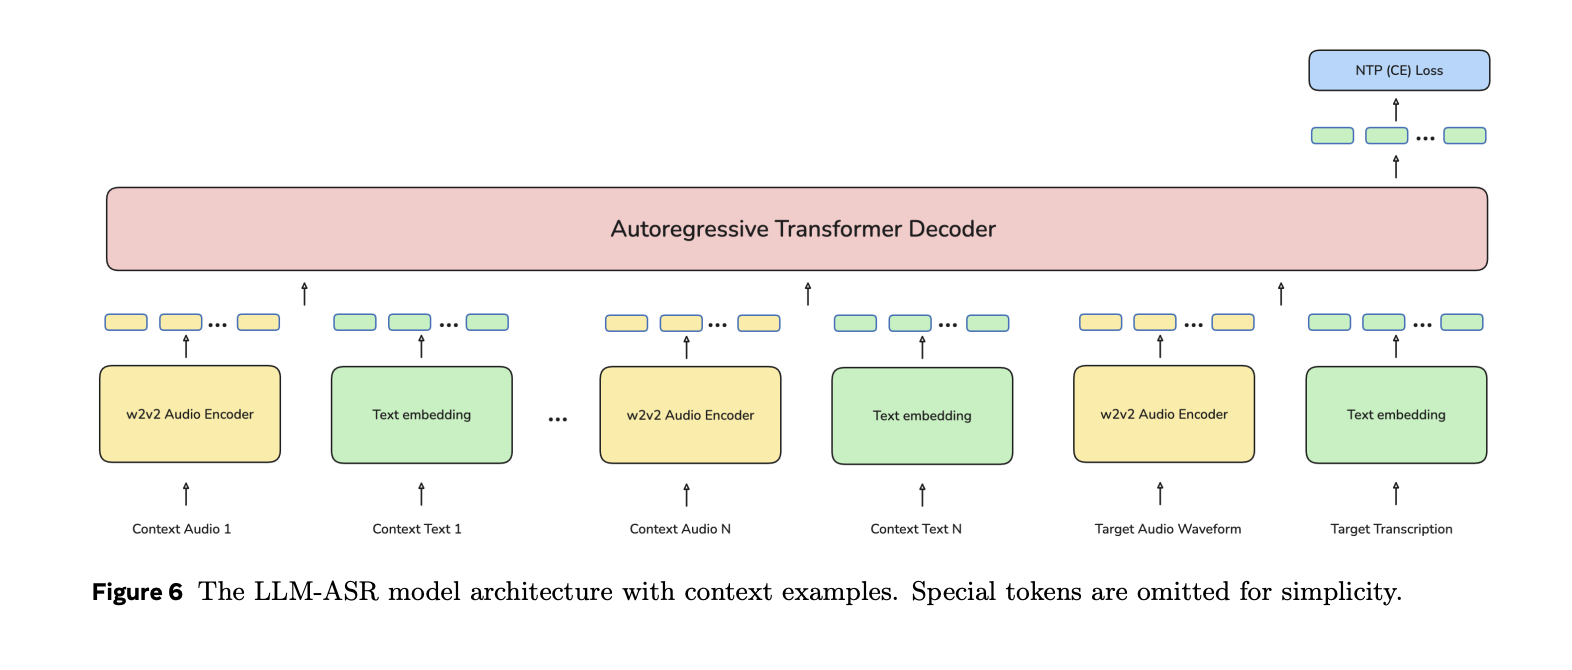
LLM ASR stacks a Transformer decoder on high of the wav2vec 2.0 encoder. The decoder is a language mannequin like Transformer that operates on character stage tokens plus particular tokens equivalent togs(x), gt(the place), gt(y), gt( ) gsis the speech encoder andgtis the textual content embedding matrix. The LLM ASR household ranges from about 1.63B parameters foromniASR_LLM_300Mto 7,801,041,536 parameters foromniASR_LLM_7B. A separateomniASR_LLM_7B_ZScheckpoint with 7,810,900,608 parameters is used for zero shot ASR.
All LLM ASR fashions help optionally available language conditioning. Languages are represented as {language_code}_{script} equivalent to eng_Latn for English in Latin script or cmn_Hans for Mandarin Chinese language in Simplified Chinese language script. A discovered embedding for the language script identifier is injected into the decoder enter. In coaching, the language ID token is typically dropped, so the mannequin also can function with out specific language tags at inference.
Zero shot ASR with context examples and SONAR
The supervised fashions cowl greater than 1,600 languages. Nonetheless, many languages nonetheless don’t have any transcribed ASR knowledge. To deal with these circumstances, Omnilingual ASR extends the LLM ASR mannequin with a zero shot mode educated with context examples.
Throughout coaching for the zero shot variant, the decoder consumes N + 1 speech textual content pairs from the identical language. The primary N pairs act as context and the ultimate pair is the goal. All pairs are embedded with the speech encoder and textual content embedding matrix, then concatenated right into a single decoder enter sequence. The loss continues to be subsequent token prediction on the goal transcription. This teaches the decoder to deduce the mapping from speech to textual content in a given language from a small immediate of in language examples.
At inference, the omniASR_LLM_7B_ZS mannequin can obtain just a few speech textual content examples from any language, together with languages not current in coaching, after which transcribe new utterances in that language with out updating weights. That is in context studying for ASR.
The system contains an instance retrieval mechanism based mostly on SONAR, a multilingual multimodal encoder that tasks audio and textual content right into a shared embedding house. The goal audio is embedded as soon as, then nearest neighbor search over a database of speech textual content pairs selects essentially the most related examples to incorporate within the context window. This SONAR based mostly choice improves zero shot efficiency in contrast with random instance choice or easy textual content similarity.
High quality and benchmarks
The omniASR_LLM_7B mannequin achieves character error price beneath 10 p.c for 78 p.c of the greater than 1,600 supported languages.
The analysis workforce studies that on multilingual benchmarks equivalent to FLEURS 102, the 7B LLM ASR mannequin outperforms the 7B CTC fashions and in addition surpasses Google USM variants in common character error price, regardless of utilizing about 4.3M unlabeled hours as an alternative of 12M and a less complicated pre coaching pipeline. This implies that scaling the wav2vec 2.0 encoder and including an LLM type decoder is an efficient path for top protection multilingual ASR.
Key Takeaways
- Omnilingual ASR gives open supply ASR protection for greater than 1,600 languages and may generalize to greater than 5,400 languages utilizing zero shot in context studying.
- The fashions are constructed on giant scale wav2vec 2.0 encoders educated on about 4.3M hours of unlabeled audio from 1,239 labeled languages plus further unlabeled speech.
- The suite contains wav2vec 2.0 encoders, CTC ASR, LLM ASR, and a devoted zero shot LLM ASR mannequin, with encoder sizes from 300M to 7B parameters and LLM ASR as much as about 7.8B parameters.
- The 7B LLM ASR mannequin achieves character error price beneath 10 p.c on 78 p.c of the greater than 1,600 supported languages, which is aggressive with or higher than prior multilingual methods in low useful resource settings.
Omnilingual ASR is a major methods stage contribution as a result of it treats multilingual ASR as an extensible framework, not a hard and fast language checklist, combining a 7B wav2vec 2.0 encoder, CTC and LLM ASR decoders, and a zero shot LLM ASR mannequin that may adapt to new languages with just a few in context examples, whereas attaining character error price beneath 10 p.c on 78 p.c of greater than 1,600 supported languages and releasing all the things underneath Apache 2.0 and CC BY 4.0. Total, this launch establishes Omnilingual ASR as essentially the most extensible open supply speech recognition mannequin presently obtainable.
Take a look at the Paper, Repo and Technical details. Be at liberty to take a look at our GitHub Page for Tutorials, Codes and Notebooks. Additionally, be happy to comply with us on Twitter and don’t neglect to hitch our 100k+ ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well.
Michal Sutter is an information science skilled with a Grasp of Science in Information Science from the College of Padova. With a stable basis in statistical evaluation, machine studying, and knowledge engineering, Michal excels at remodeling complicated datasets into actionable insights.
