


What if, instead of re-sampling one agent, you could push Gemini-2.5 Pro to 34.1% on HLE by mixing 12–15 tool-using agents that share notes and stop early? Google Cloud AI Research was launched with collaboration from MIT and Harvard as well as Google DeepMind. TUMIX is a tool-use mixture.—a test-time framework that ensembles heterogeneous agent styles (text-only, code, search, guided variants) and lets them Over a couple of rounds, share your intermediate responses“, Early stop Judges who are LLM-based can be used to assess the quality of LLM judges. This results in higher accuracy and lower costs on benchmarks that require hard reasoning, such as HLE, GPQA-Diamond” AIME (AIME 2024/2025)..

What is new about the different?
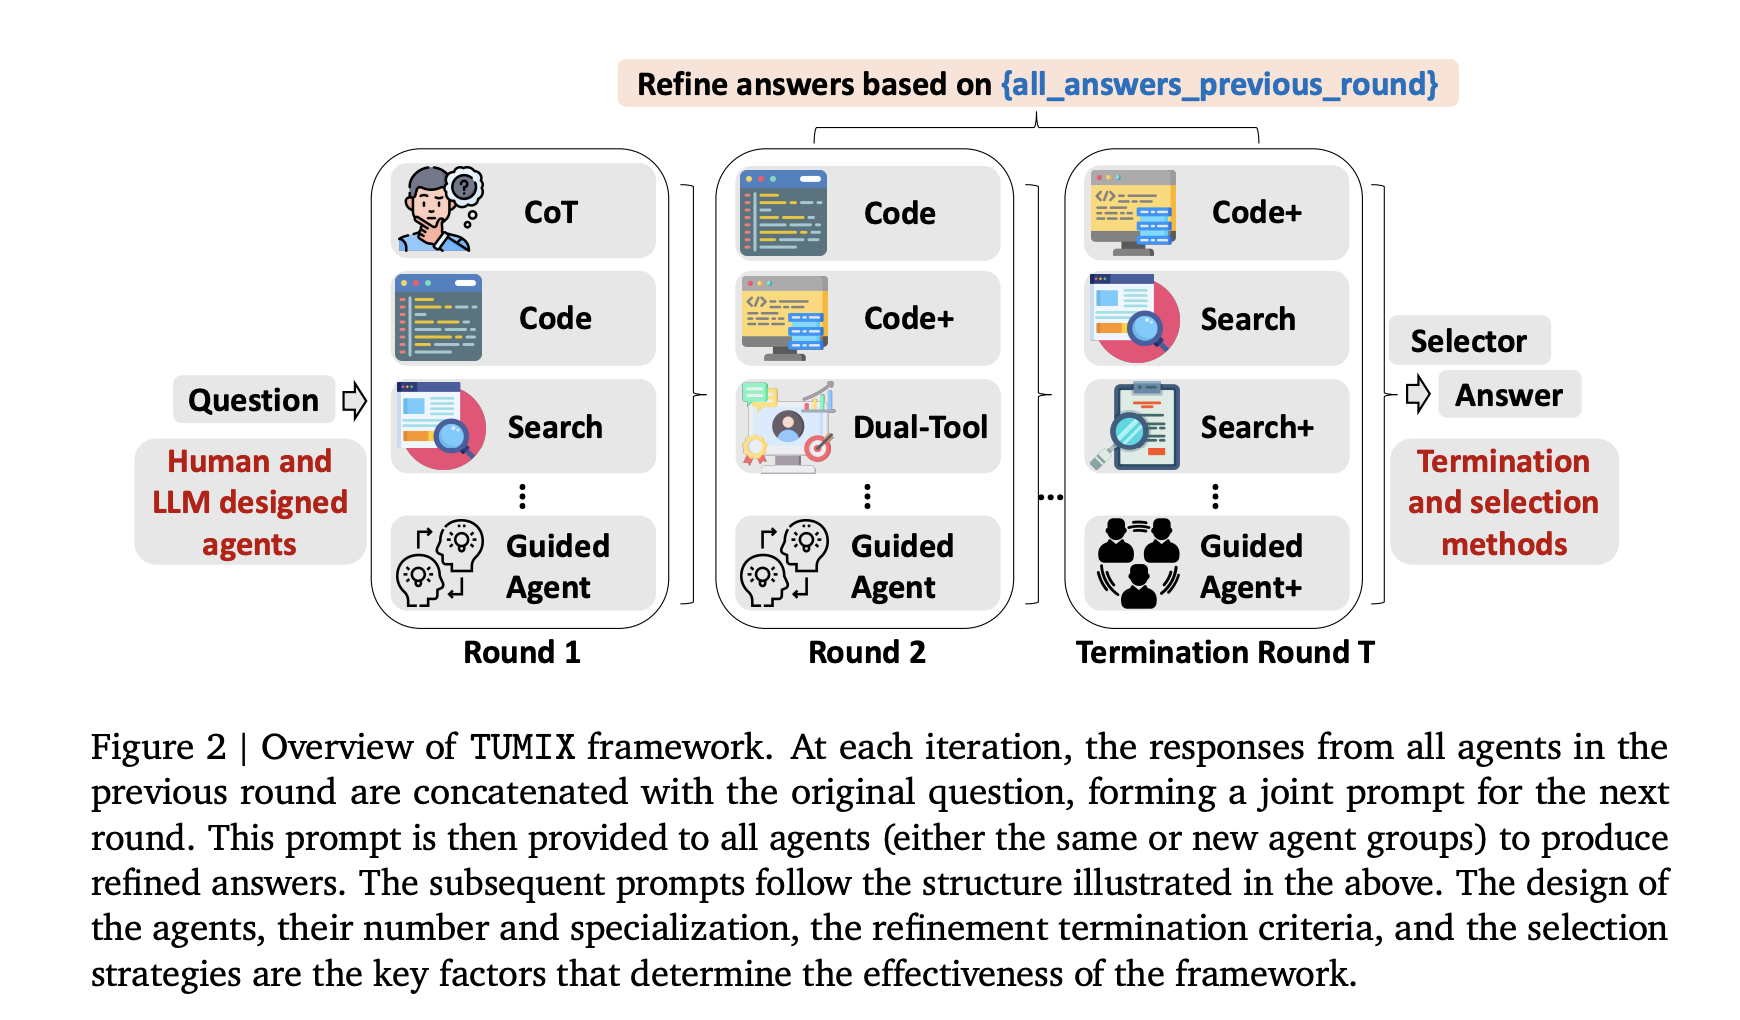
- Not just more samples, but a mix of styles.: TUMIX runs Agent styles 15 Chain-of-Thought, code execution, Web search, Dual-Tool Agents, and Guided Variants are all covered. Every agent is shown the question, and then other agents’ answers. They can refine their answer. It’s a lot of fun. message-passing raises average accuracy early while diversity gradually collapses—so stopping matters.
- The Adaptive Early-TerminationYou can also find out more about. LLM-as-Judge Once answers are in strong agreement (using a round minimum), refinement is halted. It preserves accuracy At 49% the cost of inference Due to the heavier tokens in late rounds, the cost of tokens drops by 46% compared with fixed-round refinement.
- Agents with auto-designed designsThe base LLM is prompted to go beyond human-crafted agents by TUMIX. Generate new agent typesCombining the two sets will yield an Additional +1.2% Average lift at no extra cost Average lift without extra cost “sweet spot” You can learn more about it here. ~12–15 agent styles.
How Does It Work?
TUMIX runs a group of heterogeneous agents—text-only Chain-of-Thought, code-executing, web-searching, and guided variants—in parallel, then iterates a small number of refinement rounds where each agent conditions on the original question plus the other agents’ prior rationales and answers (structured note-sharing). After each round, an LLM-based judge evaluates consensus/consistency to decide Early terminationThis design uses a mixture of tools to achieve the final result. If the confidence level is low, a second round is initiated. The design of this mixture of tools trades the brute force resampling in favor Diverse reasoning paths, improving coverage of correct candidates while controlling token/tool budgets; empirically, benefits saturate around 12–15 agent styles, and stopping early preserves diversity and lowers cost without sacrificing accuracy
Discuss the Results
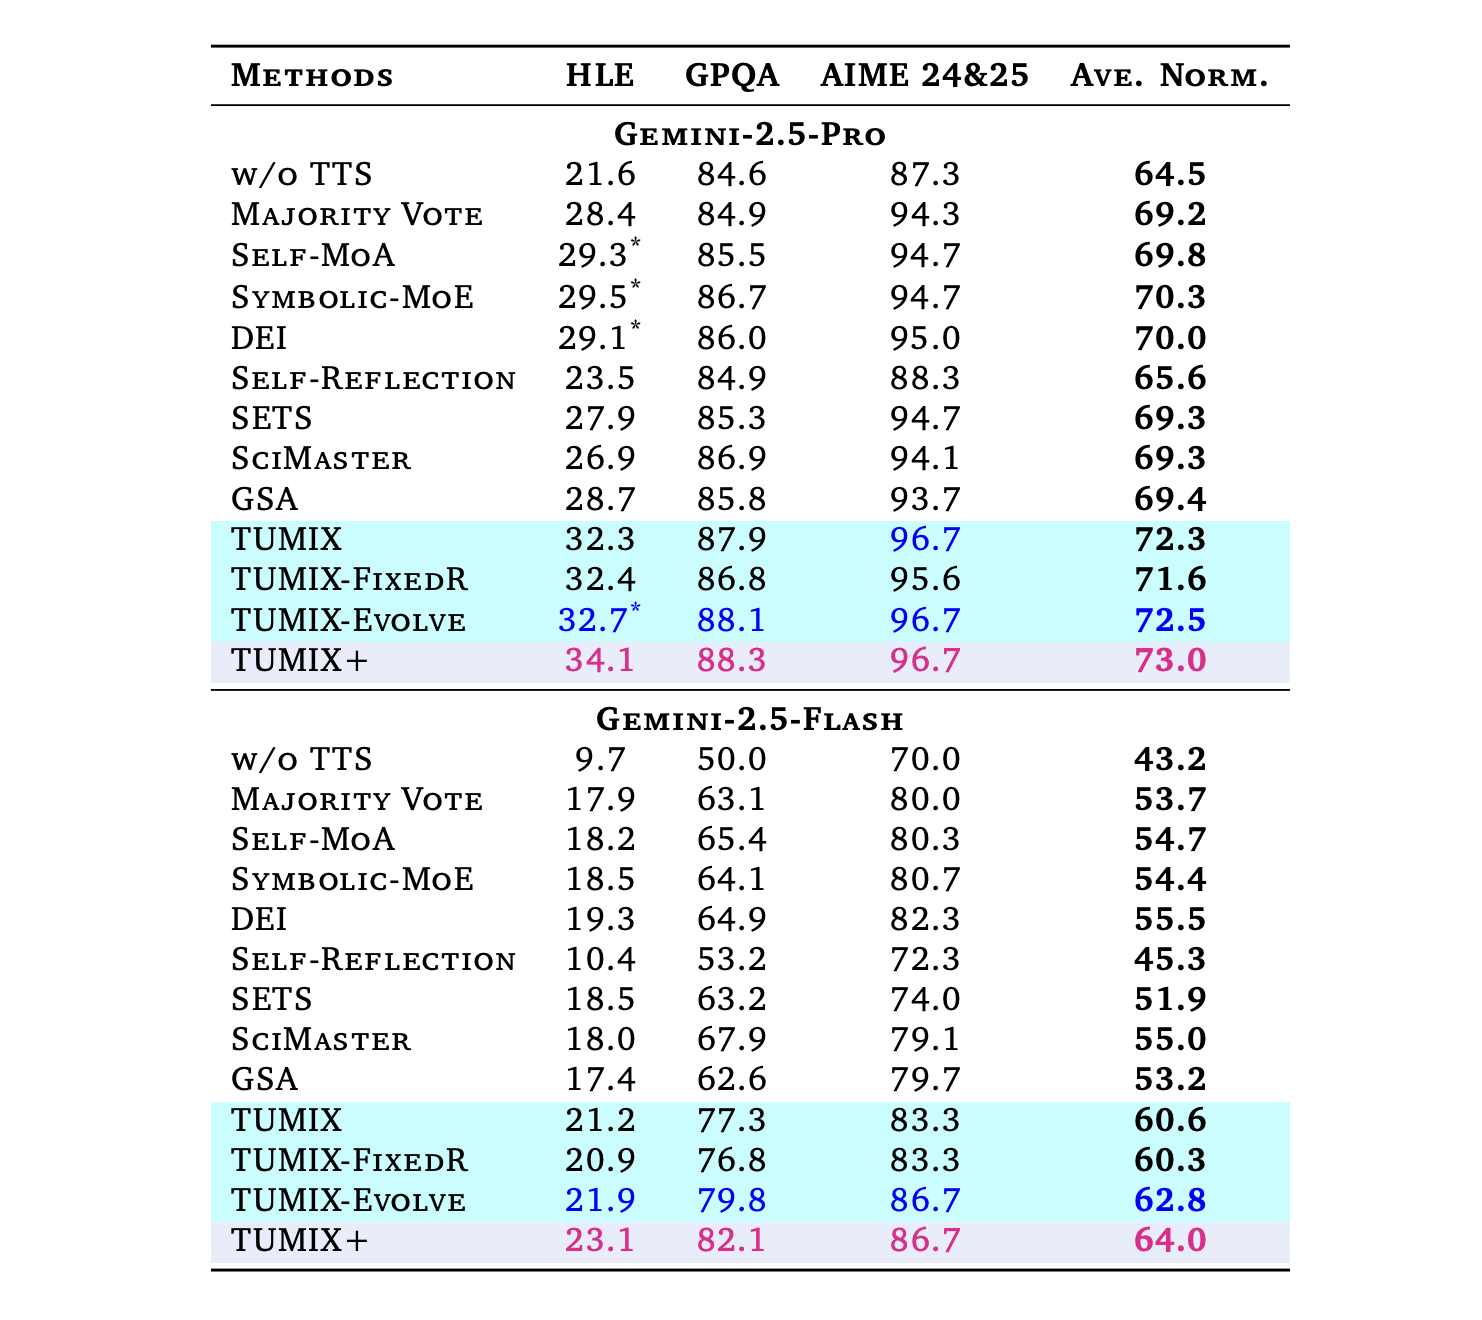
Inference Budgets: Under similar inference budgets compared to baselines with strong tools (SelfMoA; Symbolic MoE, DEI; SciMaster and GSA); TUMIX The yields best average accuracyA scaled-down variantTUMIX+() Pushes forward with more computing power
- Humanity’s Last Examination (HLE) Pro: 21.6% → 34.1% (TUMIX+); Flash: 9.7% → 23.1%.
The benchmark will consist of 2,500 difficult questions in multiple domains, and be completed by 2025. - GPQA-Diamond: Up to Pro 88.3%Flash: Up to 82.1%. (GPQA Diamond is a subset of 198 difficult questions written by domain experts.
- AIME 2024/25 Pro: 96.7%; Flash: 86.7% Test TUMIX+ at the test time.
Across tasks, The TUMIX test time scaling average is +3.55% above the previous tool-augmented baseline.” +7.8% / +17.4% No-scaling in Pro/Flash respectively.
TUMIX, a Google product that frames testing time scaling as a problem of search over tool policies heterogeneous to the brute force sampling approach. The parallel committee (text, code, search) improves candidate coverage, while the LLM-judge enables early-stop that preserves diversity and reduces token/tool spend—useful under latency budgets. The HLE gains (34.1% with Gemini-2.5 Pro) align with the benchmark’s finalized 2,500-question design, and the ~12–15 agent styles “sweet spot” indicates selection—not generation—is the limiting factor.
Take a look at the Paper. Please feel free to browse our GitHub Page for Tutorials, Codes and Notebooks. Also, feel free to follow us on Twitter Don’t forget about our 100k+ ML SubReddit Subscribe Now our Newsletter. Wait! What? now you can join us on telegram as well.

Asif Razzaq serves as the CEO at Marktechpost Media Inc. As an entrepreneur, Asif has a passion for harnessing Artificial Intelligence’s potential to benefit society. Marktechpost is his latest venture, a media platform that focuses on Artificial Intelligence. It is known for providing in-depth news coverage about machine learning, deep learning, and other topics. The content is technically accurate and easy to understand by an audience of all backgrounds. Over 2 million views per month are a testament to the platform’s popularity.
