

This tutorial will show you how to create a custom e-mail template. Microsoft’s PresidioThe open-source framework is designed to detect, analyze, and anonymousize personally identifiable information in text. Presidio was built using the lightweight spaCy NLP libraries, which makes it modular and easy to integrate in real-time pipelines and applications.
This section will show you how to:
- Presidio Packages: Install and setup
- Detect commonly used PII, such as credit card numbers, names and phone numbers
- Customize recognizers to be used for specific entities, e.g. PAN and Aadhaar
- Custom anonymizers can be created and registered (like pseudonyms or hashing).
- Reuse anonymization mappings for consistent re-anonymization
Installing the Libraries
You’ll also need the following libraries installed to start using Presidio:
- presidio-analyzer: This library is responsible for detecting PII in text by using both built-in recognizers and custom ones.
- presidio-anonymizer: This library contains tools for anonymizing (e.g. replace, redact or hash) detected PII by using configurable operators.
- spaCy NLP model (en_core_web_lg): Presidio relies on spaCy to perform natural language processing, such as named entity recognition. For English-language PII, the en_core_web_lg provides accurate results.
Install presidio analyzer presidio anonymizer with pip
Download spacy en_core_web_lg using python with -m.
If you use Jupyter/Colab, it may be necessary to restart your session in order to install libraries.
Presidio Analyzer
Basic PII Detection
This block initializes the Presidio Analyzer Engine, and runs a simple analysis in order to identify a U.S. telephone number within a text sample. For cleaner output, we also suppress the lower-level warnings of Presidio’s library.
AnalyzerEngine uses spaCy NLP and recognizers predefined to search for sensitive entities in the input text. This example specifies PHONE_NUMBER to be the target.
import logging
logging.getLogger("presidio-analyzer").setLevel(logging.ERROR)

From presidio_analyzer, import AnalyzerEngine

Setup the engine. Load the NLP module by default (the SpaCy model).
analyzer = AnalyzerEngine()

Get results by calling the Call Analyzer
results = analyzer.analyze(text="My phone number is 212-555-5555",
                           entities=["PHONE_NUMBER"],
                           language="en")
print(results)
Create a Customized PHI Recognizer (Academic titles) with a List of Denys
This code block demonstrates how to use a simple list of deny terms in Presidio to create a custom PII recognition. It is ideal for detecting academic titles, such as “e.g. “Dr.”, “Prof.”). The analyzer scans input text using the recognizer, which is stored in Presidio’s registry.
Presidio supports a variety of other approaches, including regex patterns, NLP, external recognizers, and NLP-based models. You can find more information on the advanced methods in the Presidio documentation: Adding Custom Recognizers.
Presidio Analyzer
Basic PII Detection
This block initializes the Presidio Analyzer Engine, and runs a simple analysis in order to identify a U.S. telephone number within a text sample. For cleaner output, we also suppress the lower-level warnings of Presidio’s library.
AnalyzerEngine uses spaCy NLP and recognizers predefined to search for sensitive entities in the input text. This example specifies PHONE_NUMBER to be the target.
import logging
logging.getLogger("presidio-analyzer").setLevel(logging.ERROR)

From presidio_analyzer, import AnalyzerEngine

# Install the engine and load the NLP (default SpaCy) module.
analyzer = AnalyzerEngine()

Get results by calling the Call Analyzer
results = analyzer.analyze(text="My phone number is 212-555-5555",
                           entities=["PHONE_NUMBER"],
                           language="en")
print(results)
Create a Custom PII Recognizer With a Block List (Academic titles)
This code block demonstrates how to use a simple list of deny terms in Presidio to create a custom PII recognition. It is ideal for detecting academic titles, such as “e.g. “Dr.”, “Prof.”). The analyzer scans input text using the recognizer, which is stored in Presidio’s registry.
Presidio is not limited to the Deny List approach. It also offers NLP and regex-based patterns as well as external recognizers. You can find more information on the advanced methods in the Presidio documentation: Adding Custom Recognizers.
Import AnalyzerEngine and RecognizerRegistry from presidio_analyzer

# Step 1: Create a custom pattern recognizer using deny_list
academic_title_recognizer = PatternRecognizer(
    supported_entity="ACADEMIC_TITLE",
    deny_list=["Dr.", "Dr", "Professor", "Prof."]
)

# Step 2. Add to registry
Register = RecognizerRegistry()
registry.load_predefined_recognizers()
registry.add_recognizer(academic_title_recognizer)

# Create the analyzer engine using updated registry
analyzer = AnalyzerEngine(registry=registry)

# Step 4: Analysis of text
Text "Prof. John Smith is meeting with Dr. Alice Brown."
results = analyzer.analyze(text=text, language="en")

For example:
    print(result)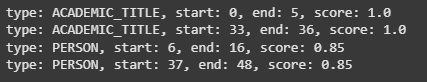
Presidio Anonymizer
This code block demonstrates the use of Presidio Anonymizer Engine for anonymizing detected PII in a specified text. In this example we define manually two PERSONs using RecognizerResult to simulate output from Presidio Analyzer. The names are represented by these entities “Bond” You can also find out more about the following: “James Bond” Sample text
Use the “replace” The operator can substitute the placeholder values for both names (“BIP”The AnonymizerEngine is notified of the anonymized data by sending an OperatorConfig containing the preferred strategy for anonymization (replace). An OperatorConfig containing the desired strategy for anonymization (replacement) is passed to the AnonymizerEngine.
The pattern is easily extensible to include other operations built in, such as “redact”, “hash”, or custom pseudonymization strategies.
from presidio_anonymizer import AnonymizerEngine
from presidio_anonymizer.entities import RecognizerResult, OperatorConfig

# Initializes the engine
engine = AnonymizerEngine()

# Use anonymize with text.
The # results of the analyzer (possibly coming from Presidio Analyzer).
# Operation to anonymize output
result = engine.anonymize(
    text="My name is Bond, James Bond",
    analyzer_results=[
        RecognizerResult(entity_type="PERSON", start=11, end=15, score=0.8),
        RecognizerResult(entity_type="PERSON", start=17, end=27, score=0.8),
    ],
    operators={"PERSON": OperatorConfig("replace", {"new_value": "BIP"})},
)

print(result)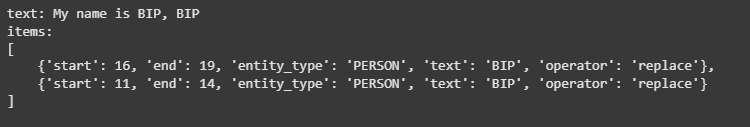
Presidio provides Custom Entity Recognition (CER), Hash-Based Anonymous and Consistent re-anonymization.
This example takes Presidio one step further, by showing:
- ✅ Using PatternRecognizers based on regex, define custom PII (such as Aadhaar or PAN) entities
- 🔐 Anonymizing data with a hash operator of your choice (ReAnonymizer).
- ♻️ Re-anonymizing the same values consistently across multiple texts by maintaining a mapping of original → hashed values
ReAnonymizer checks whether a value is already hashed, and reuses that output for consistency. This is particularly useful when anonymized data needs to retain some utility — for example, linking records by pseudonymous IDs.
Define a Custom Hash-Based Anonymizer (ReAnonymizer)
This block defines a custom operator called ReAnonymizer, which uses SHA256 hashing for anonymizing entities. It also ensures that the same input will always get the same anonymousized output because hashes are stored in a mapping shared by all.
from presidio_anonymizer.operators import Operator, OperatorType
Hashlib import
Type import Dict

class ReAnonymizer(Operator):
    """
 Anonymous text is replaced with a reusable SHA256 hash.
 Linked to a common mapping dictionary.
    """

    def operate(self, text: str, params: Dict = None) -> str:
        entity_type = params.get("entity_type", "DEFAULT")
 Get the mapping parameters by using params.get()"entity_mapping")

 If the mapping is None, then:
            raise ValueError("Missing `entity_mapping` in params")

 # Check to see if hashing is already done
 If entity_type is in the mapping, and if text is in the mapping[entity_type]:
 Return mapping[entity_type][text]

 # Hashing and Store
 "Hash =""
        mapping.setdefault(entity_type, {})[text] Hash
 Hashed return

    def validate(self, params: Dict = None) -> None:
 If "entity_mapping" "Not in params"
            raise ValueError("You must pass an 'entity_mapping' dictionary.")

    def operator_name(self) -> str:
 You can return to your original language by clicking here. "reanonymizer"

    def operator_type(self) -> OperatorType:
        return OperatorType.Anonymize
Define custom PII recognizers for Aadhaar numbers and PANs
We define two custom regex-based PatternRecognizers — one for Indian PAN numbers and one for Aadhaar numbers. These are able to detect custom PII entity in your text.
Import AnalyzerEngine and PatternRecognizer from Presidio_analyzer.
Defining custom recognition

pan_recognizer = PatternRecognizer(

    supported_entity="IND_PAN",

    name="PAN Recognizer",

    patterns=[Pattern(name="pan", regex=r"b[A-Z]
