


In the current AI landscape, the ‘context window’ has become a blunt instrument. It was told to us that expanding the memory for a Frontier model would solve the retrieval problems. But as any AI professionals building RAG (Retrieval-Augmented Generation) systems knows, stuffing a million tokens into a prompt often leads to higher latency, astronomical costs, and a ‘lost in the middle’ reasoning failure that no amount of compute seems to fully solve.
Chroma, a company responsible for the widely used open-source Vector database, has taken a new, surgical approach. They released Context-1A 20B parameter search agent designed as a retrieval subagent.
Rather than trying to be a general-purpose reasoning engine, Context-1 is a highly optimized ‘scout.’ Context-1 is designed to perform one task: to find supporting documents to complex multi-hop questions and to pass them on to an downstream frontier model to get the answer.
Agentic Subagents: The rise of the Agentic Subagent
Context-1 derives from gpt-oss-20BChroma’s Mixture of Experts architecture has been fine-tuned via a combination of Reinforcement Learning and Supervised Finesse Tuning. CISPO The staged Curriculum Optimization
You’re not only trying to get chunks back; you’re also trying to complete a “Sequential Reasoning” is a test of reasoning.. Context-1 is not limited to a single vector index. Context-1 breaks down the query to subqueries (on average 2.56 requests per round) and searches iteratively the corpus.
This is the key take-away for AI professionals: The search engine is decoupled from the generation. In the traditional RAG pipe, it is the developer who manages retrieval logic. Context-1 transfers this responsibility from the developer to Context-1. It is a model that operates within a special agent harness, which allows it to interact with tools. search_corpus (hybrid BM25 + dense search), grep_corpus The (regex) and read_document.
It’s the Killer Feature! Self-editing Context
Context-1’s most significant technical innovation is Context for Self-Editing.
As an agent gathers information over multiple turns, its context window fills up with documents—many of which turn out to be redundant or irrelevant to the final answer. General models eventually ‘choke’ on this noise. However, Context-1 has been taught with a Cutting accuracy 0.94.
In the middle of a search, the model evaluates its acquired context and executes proactive. prune_chunks Toss out irrelevant passages. This ‘soft limit pruning’ keeps the context window lean, freeing up capacity for deeper exploration and preventing the ‘context rot’ that plagues longer reasoning chains. The specialized model can maintain high retrieval within a 32k context even when traversing datasets which would normally require larger windows.
Building the ‘Leak-Proof’ Benchmark: context-1-data-gen
To train and evaluate a model on multi-hop reasoning, you need data where the ‘ground truth’ is known and requires multiple steps to reach. Chroma’s tool to resolve this problem has been open-sourced: The context-1-data-gen repository.
It generates tasks that are synthetic and multi-hop across four distinct domains.
- Web: Open web research in multi-step tasks.
- SEC: SEC Filings (SEC 10-K/20-F): Finance Tasks
- Patents: Focus on USPTO’s prior art search.
- Email: The Epstein Files and Enron Corpus can be used to search for information.
Data generation is a process that follows an organized and rigorous methodology. Explore → Verify → Distract → Index pattern. It generates ‘clues’ and ‘questions’ where the answer can only be found by bridging information across multiple documents. By mining ‘topical distractors’—documents that look relevant but are logically useless—Chroma ensures that the model cannot ‘hallucinate’ its way to a correct answer through simple keyword matching.
GPT-5: Performance that is faster, cheaper, and competitive with GPT-5
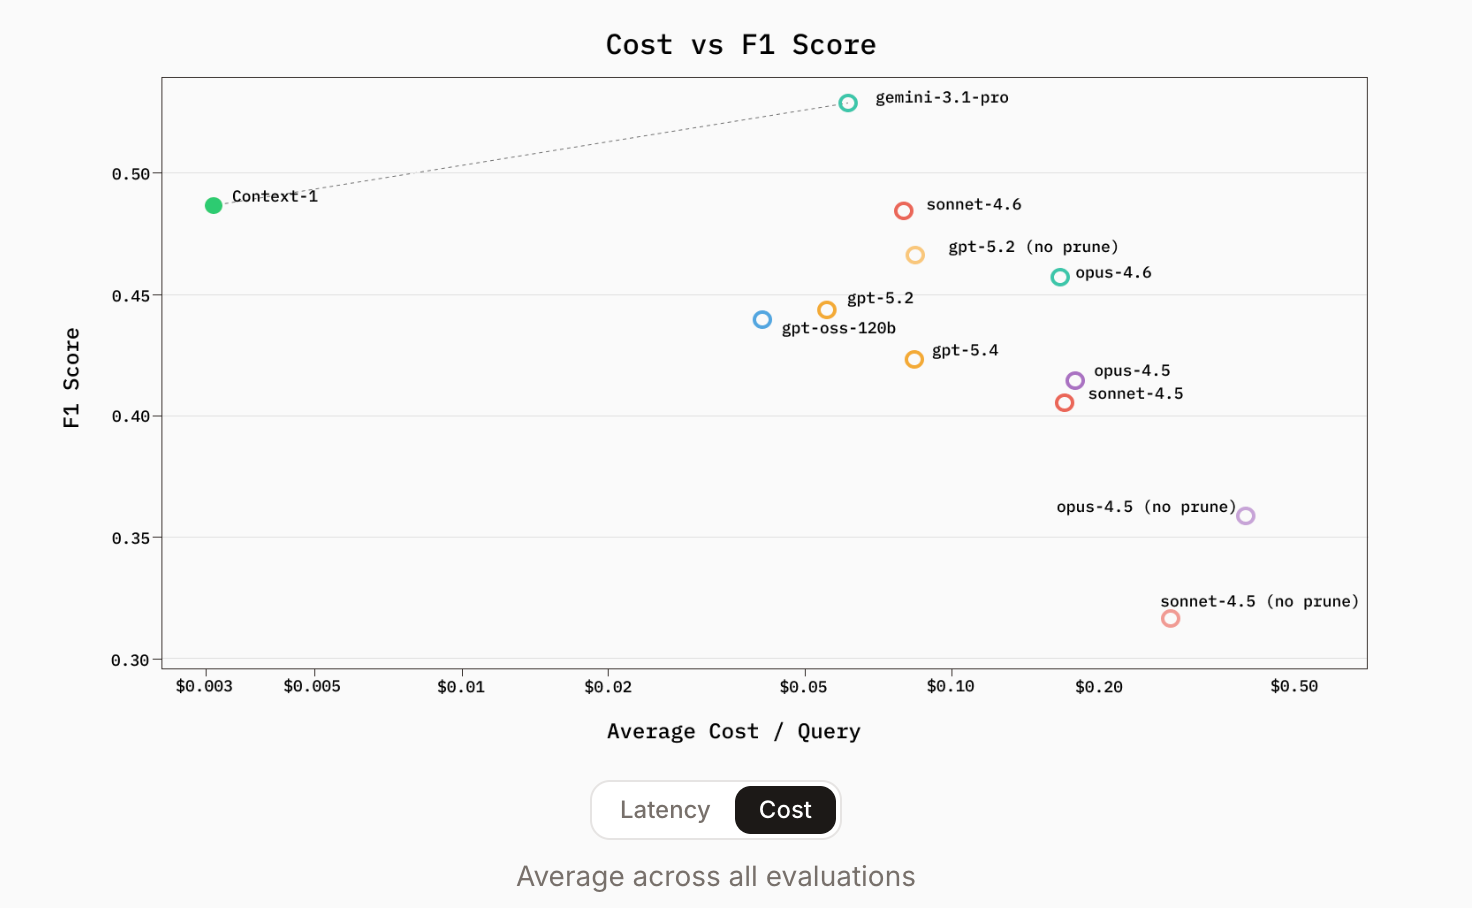
The benchmark results released by Chroma are a reality check for the ‘frontier-only’ crowd. Context-1’s performance was compared with 2026-era giants, including gpt-oss-120b, gpt-5.2, gpt-5.4And the Sonnet/Opus: 4.5 and 4.4.6 families.
Public benchmarks such as BrowseComp-Plus, SealQA, FRAMESThen, HotpotQAContext-1 has demonstrated retrieval results comparable to models of the frontier that are several orders-of magnitude more powerful.
Efficiency gains are what most motivates AI developers.
- Speed: Context-1 provides a range of Faster inferences 10x The Frontier model is more general purpose than other models.
- Cost: About 25x cheaper Run for the same retrieval task.
- Pareto Frontier: By using a ‘4x’ configuration—running four Context-1 agents in parallel and merging results via reciprocal rank fusion—it matches the accuracy of a single GPT-5.4 run at a fraction of the compute.
The ‘performance cliff’ identified isn’t about token length alone; it’s about hop-count. General models can’t keep up with the increasing number of reasoning stages. Context-1’s specialized training allows it to navigate these deeper chains more reliably because it isn’t distracted by the ‘answering’ task until the search is concluded.

The Key Takeaways
- The ‘Scout’ Model Strategy: Context-1, which is a 20B parameter agentic model derived from the gpt oss-20B, was designed as a retrieval assistant. It proves that a lean and specialized model outperforms massive, general-purpose LLMs when it comes to multi-hop searches.
- Self-Editing Context: To solve the problem of ‘context rot,’ the model features a pruning accuracy of 0.94, allowing it to proactively discard irrelevant documents mid-search to keep its context window focused and high-signal.
- Leak-Proof Benchmarking: This open-source
context-1-data-gentool uses a synthetic ‘Explore → Verify → Distract’ pipeline to create multi-hop tasks in Web, SEC, Patent, and Email domains, ensuring models are tested on reasoning rather than memorized data. - Decoupled Efficiency Context-1, which focuses solely on retrieval of information, achieves 10x quicker inferences and 25x less costs than frontiers models such as GPT-5.4 while achieving the same accuracy for complex benchmarks, like HotpotQA or FRAMES.
- This Future is a Tiered RAG Future This release champions a tiered architecture where a high-speed subagent curates a ‘golden context’ for a downstream frontier model, effectively solving the latency You can also find out more about the following: reasoning failures of massive, unmanaged context windows.
Check out the Repo and Technical details. Also, feel free to follow us on Twitter Don’t forget about our 120k+ ML SubReddit Subscribe Now our Newsletter. Wait! What? now you can join us on telegram as well.
