Introduction: The Rising Want for AI Guardrails
As massive language fashions (LLMs) develop in functionality and deployment scale, the danger of unintended habits, hallucinations, and dangerous outputs will increase. The latest surge in real-world AI integrations throughout healthcare, finance, training, and protection sectors amplifies the demand for strong security mechanisms. AI guardrails—technical and procedural controls making certain alignment with human values and insurance policies—have emerged as a vital space of focus.
The Stanford 2025 AI Index reported a 56.4% jump in AI-related incidents in 2024—233 circumstances in whole—highlighting the urgency for strong guardrails. In the meantime, the Future of Life Institute rated major AI firms poorly on AGI security planning, with no agency receiving a ranking larger than C+.
What Are AI Guardrails?
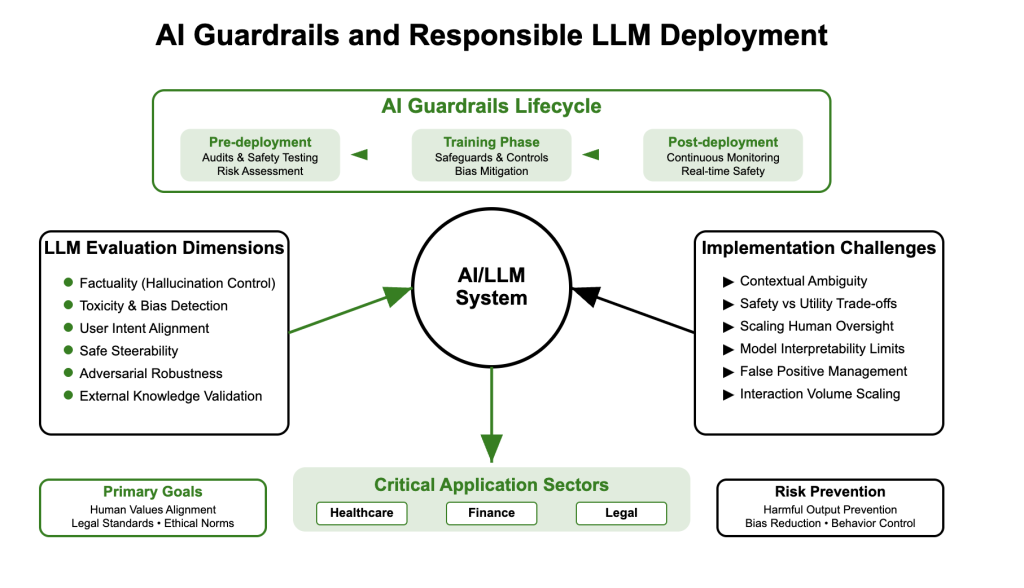
AI guardrails seek advice from system-level security controls embedded throughout the AI pipeline. These will not be merely output filters, however embody architectural choices, suggestions mechanisms, coverage constraints, and real-time monitoring. They are often labeled into:
- Pre-deployment Guardrails: Dataset audits, mannequin red-teaming, coverage fine-tuning. For instance, Aegis 2.0 includes 34,248 annotated interactions across 21 safety-relevant categories.
- Coaching-time Guardrails: Reinforcement studying with human suggestions (RLHF), differential privacy, bias mitigation layers. Notably, overlapping datasets can collapse these guardrails and allow jailbreaks.
- Put up-deployment Guardrails: Output moderation, steady analysis, retrieval-augmented validation, fallback routing. Unit 42’s June 2025 benchmark revealed high false positives moderately instruments.
Reliable AI: Rules and Pillars
Reliable AI just isn’t a single approach however a composite of key ideas:
- Robustness: The mannequin ought to behave reliably underneath distributional shift or adversarial enter.
- Transparency: The reasoning path have to be explainable to customers and auditors.
- Accountability: There must be mechanisms to hint mannequin actions and failures.
- Equity: Outputs shouldn’t perpetuate or amplify societal biases.
- Privateness Preservation: Strategies like federated studying and differential privateness are vital.
Legislative concentrate on AI governance has risen: in 2024 alone, U.S. businesses issued 59 AI-related regulations across 75 countries. UNESCO has additionally established global ethical guidelines.
LLM Analysis: Past Accuracy
Evaluating LLMs extends far past conventional accuracy benchmarks. Key dimensions embody:
- Factuality: Does the mannequin hallucinate?
- Toxicity & Bias: Are the outputs inclusive and non-harmful?
- Alignment: Does the mannequin observe directions safely?
- Steerability: Can it’s guided based mostly on person intent?
- Robustness: How effectively does it resist adversarial prompts?
Analysis Strategies
- Automated Metrics: BLEU, ROUGE, perplexity are nonetheless used however inadequate alone.
- Human-in-the-Loop Evaluations: Professional annotations for security, tone, and coverage compliance.
- Adversarial Testing: Utilizing red-teaming strategies to emphasize check guardrail effectiveness.
- Retrieval-Augmented Analysis: Reality-checking solutions towards exterior data bases.
Multi-dimensional instruments similar to HELM (Holistic Evaluation of Language Models) and HolisticEval are being adopted.
Architecting Guardrails into LLMs
The mixing of AI guardrails should start on the design stage. A structured method contains:
- Intent Detection Layer: Classifies doubtlessly unsafe queries.
- Routing Layer: Redirects to retrieval-augmented era (RAG) techniques or human overview.
- Put up-processing Filters: Makes use of classifiers to detect dangerous content material earlier than remaining output.
- Suggestions Loops: Consists of person suggestions and steady fine-tuning mechanisms.
Open-source frameworks like Guardrails AI and RAIL present modular APIs to experiment with these parts.
Challenges in LLM Security and Analysis
Regardless of developments, main obstacles stay:
- Analysis Ambiguity: Defining harmfulness or equity varies throughout contexts.
- Adaptability vs. Management: Too many restrictions scale back utility.
- Scaling Human Suggestions: High quality assurance for billions of generations is non-trivial.
- Opaque Mannequin Internals: Transformer-based LLMs stay largely black-box regardless of interpretability efforts.
Current studies present over-restricting guardrails usually leads to excessive false positives or unusable outputs (source).
Conclusion: Towards Accountable AI Deployment
Guardrails will not be a remaining repair however an evolving security web. Reliable AI have to be approached as a systems-level problem, integrating architectural robustness, steady analysis, and moral foresight. As LLMs acquire autonomy and affect, proactive LLM analysis methods will function each an moral crucial and a technical necessity.
Organizations constructing or deploying AI should deal with security and trustworthiness not as afterthoughts, however as central design targets. Solely then can AI evolve as a dependable associate somewhat than an unpredictable threat.
FAQs on AI Guardrails and Accountable LLM Deployment
1. What precisely are AI guardrails, and why are they vital?
AI guardrails are complete security measures embedded all through the AI growth lifecycle—together with pre-deployment audits, coaching safeguards, and post-deployment monitoring—that assist forestall dangerous outputs, biases, and unintended behaviors. They’re essential for making certain AI techniques align with human values, authorized requirements, and moral norms, particularly as AI is more and more utilized in delicate sectors like healthcare and finance.
2. How are massive language fashions (LLMs) evaluated past simply accuracy?
LLMs are evaluated on a number of dimensions similar to factuality (how usually they hallucinate), toxicity and bias in outputs, alignment to person intent, steerability (potential to be guided safely), and robustness towards adversarial prompts. This analysis combines automated metrics, human critiques, adversarial testing, and fact-checking towards exterior data bases to make sure safer and extra dependable AI habits.
3. What are the largest challenges in implementing efficient AI guardrails?
Key challenges embody ambiguity in defining dangerous or biased habits throughout completely different contexts, balancing security controls with mannequin utility, scaling human oversight for enormous interplay volumes, and the inherent opacity of deep studying fashions which limits explainability. Overly restrictive guardrails can even result in excessive false positives, irritating customers and limiting AI usefulness.
Michal Sutter is an information science skilled with a Grasp of Science in Knowledge Science from the College of Padova. With a stable basis in statistical evaluation, machine studying, and information engineering, Michal excels at remodeling advanced datasets into actionable insights.